<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.9.5">Jekyll</generator><link href="https://blog.veladan.org/feed.xml" rel="self" type="application/atom+xml" /><link href="https://blog.veladan.org/" rel="alternate" type="text/html" /><updated>2026-11-01T22:01:10+00:00</updated><id>https://blog.veladan.org/feed.xml</id><title type="html">Veladan Programming Blog</title><subtitle>...for all the programming issues I found.</subtitle><entry><title type="html">How Revolut cut AI coding costs 90% with self-hosted open models</title><link href="https://blog.veladan.org/2026/11/01/revolut-cut-ai-coding-costs-self-hosted-glm.html" rel="alternate" type="text/html" title="How Revolut cut AI coding costs 90% with self-hosted open models" /><published>2026-11-01T05:00:00+00:00</published><updated>2026-11-01T05:00:00+00:00</updated><id>https://blog.veladan.org/2026/11/01/revolut-cut-ai-coding-costs-self-hosted-glm</id><content type="html" xml:base="https://blog.veladan.org/2026/11/01/revolut-cut-ai-coding-costs-self-hosted-glm.html"><![CDATA[<p>I watched <a href="https://www.youtube.com/watch?v=Ok6QdZHCcI8">“How Revolut Cut AI Coding Costs 90% With Self-Hosted Open Models”</a> — David Abitbol, who leads AI operations at Revolut, speaking at AI Engineer New York. His framing: <em>“Shipping like a startup, regulated like a bank.”</em> It is a dense technical talk, and almost every number in it is relevant to anyone running local models for agentic coding, so here are the points that matter.</p>

<h2 id="the-rollout-with-receipts">The rollout, with receipts</h2>

<p>Revolut (80M customers, 45 markets) tracked a sample of 2,000 engineers for about a year:</p>

<table>
  <thead>
    <tr>
      <th>Period</th>
      <th>Tool</th>
      <th>Lead time</th>
      <th>Coding time</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Jan 2025</td>
      <td>Gemini</td>
      <td>+10%</td>
      <td>+20%</td>
    </tr>
    <tr>
      <td>Feb 2025 – Jan 2026</td>
      <td>Claude Code</td>
      <td>minimal at launch</td>
      <td>minimal at launch</td>
    </tr>
    <tr>
      <td>Apr 2026</td>
      <td>Self-hosted GLM 5.1</td>
      <td><strong>+70%</strong></td>
      <td><strong>+60%</strong></td>
    </tr>
  </tbody>
</table>

<p>Two details worth pausing on. First, Claude Code showed little <em>measurable</em> impact at first while engineers were spending $1,000–$10,000/month, which is why the rollout came with strict budget caps. Second, the asymmetry of the GLM numbers: the bigger gain landed on <strong>lead time</strong>, not coding time. His explanation is that the bottleneck in engineering is not typing code — it is the surrounding work (inbox triage, Jira, Confluence). When tokens are effectively unlimited, engineers stop rationing them for the hardest task or the end of the quarter.</p>

<p>The current posture: self-hosted open source is the default, billing is flat with no month-to-month bill shock, and frontier models (Codex, Claude Code, Gemini) are the exception for the hardest tasks.</p>

<h2 id="the-economics">The economics</h2>

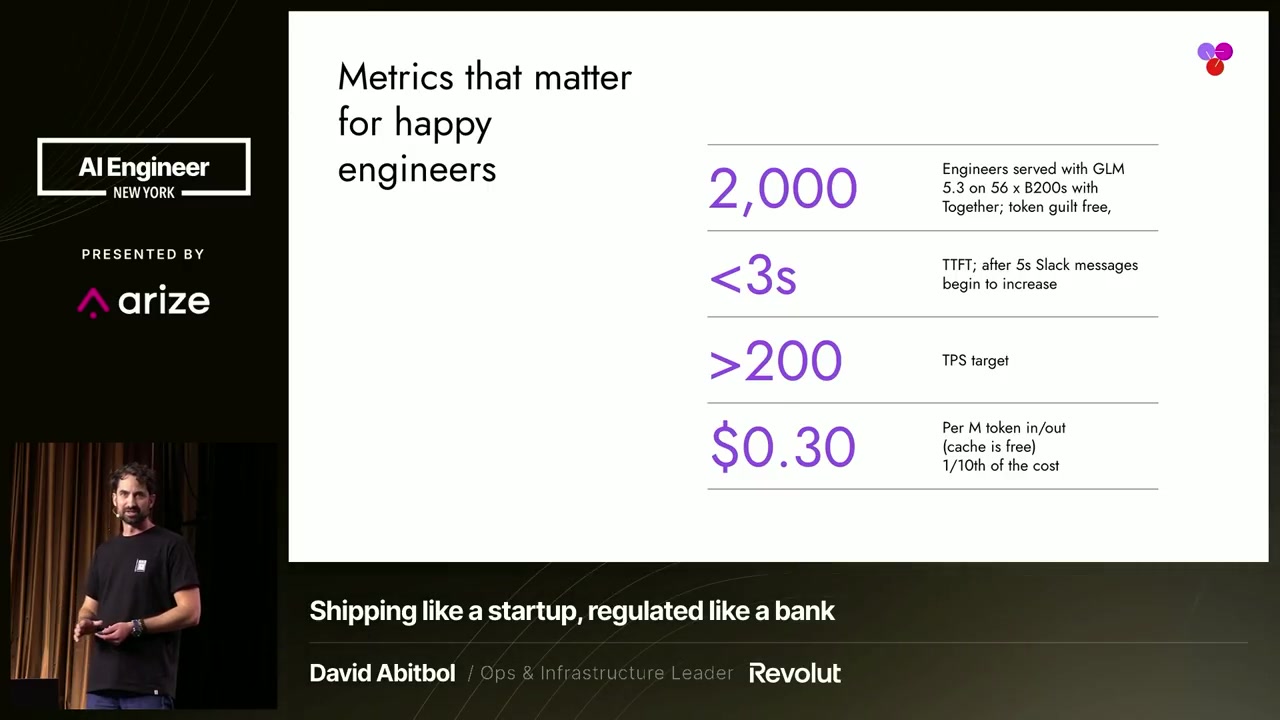
<p><img src="/assets/revolut-glm-metrics.jpg" alt="Metrics that matter for happy engineers: 2,000 engineers, &lt;3s TTFT, &gt;200 TPS, $0.30 per million tokens" /></p>

<p>The capacity math: serving 2,000 engineers on GLM 5.3 — an 800-billion-parameter model — takes roughly <strong>56 B200 GPUs</strong> (dedicated, hosted with Together AI). The headline numbers:</p>

<ul>
  <li><strong>$0.30 per million tokens blended</strong> (in/out, cache is free) — the invoice is <strong>one tenth</strong> of what they were paying Anthropic and OpenAI.</li>
  <li>Latency targets are empirical, not theoretical: <strong>TTFT under 3 seconds</strong>, because past 5 seconds <em>“my Slack inbox starts to blow up.”</em></li>
  <li><strong>Throughput barely matters</strong> for interactivity: 200 TPS is fine, because engineers now run tasks in parallel and check back when they finish instead of watching tokens stream. After 5 p.m., when the GPUs are idle, they get 800 TPS.</li>
</ul>

<h2 id="resist-scaling-tune-first">Resist scaling, tune first</h2>

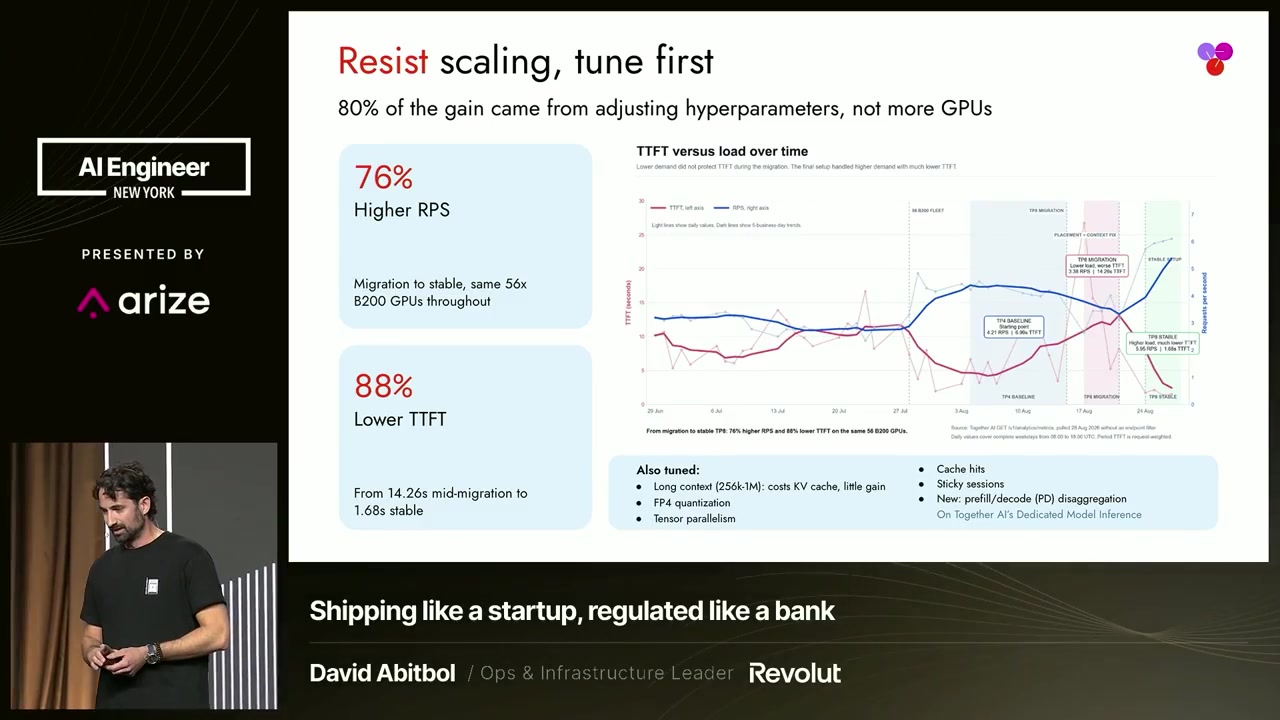
<p>This is the slide I would tattoo on the ops team’s wall:</p>

<p><img src="/assets/revolut-resist-scaling.jpg" alt="Resist scaling, tune first: 76% higher RPS and 88% lower TTFT on the same 56 GPUs" /></p>

<p>80% of the performance gain came from adjusting hyperparameters, <strong>not more GPUs</strong>. Same 56 B200s from April to August: requests per second up 76% (3 → 7+) and time-to-first-token down 88% (14.26s → 1.68s stable). Dropping weights onto GPUs and calling it a day produces terrible performance; the configuration is the product.</p>

<p>His tuning checklist, roughly in order of contrarian value:</p>

<ul>
  <li><strong>Long context is a scam.</strong> Even if the model advertises 1M tokens, the workload needs 256K — and serving more costs KV cache for little gain.</li>
  <li><strong>FP4 is the floor on Blackwell.</strong> Going from FP4 to FP8 costs about 40% more GPU footprint for zero precision gain.</li>
  <li><strong>Tensor parallelism</strong>: GLM fits on TP4, but the KV cache runs short; TP8 may serve better depending on workload.</li>
  <li><strong>Cache hit rate above 90%</strong> for coding tasks — this is why sticky sessions matter.</li>
  <li>Plus speculative decoding and prefill/decode (PD) disaggregation.</li>
</ul>

<h2 id="take-the-smarter-model-route-vision-elsewhere">Take the smarter model, route vision elsewhere</h2>

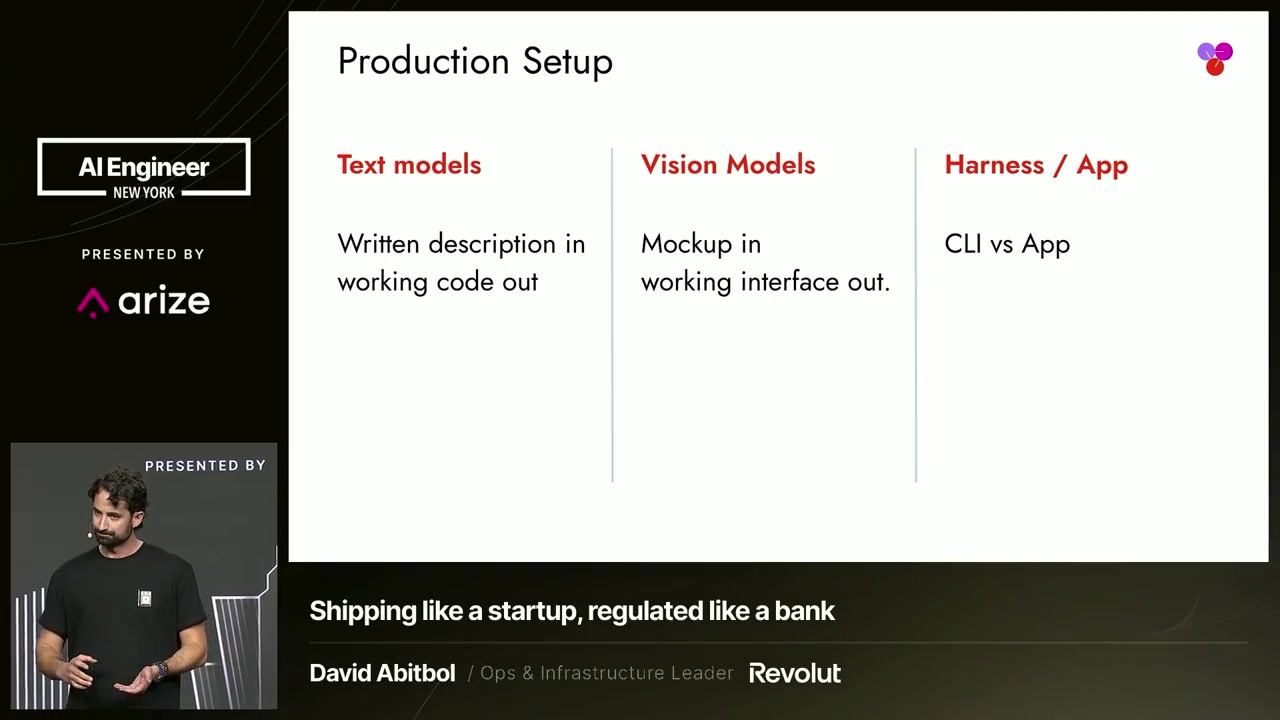
<p><img src="/assets/revolut-production-setup.jpg" alt="Production setup: text models, vision models, harness" /></p>

<p>GLM is text-only, and he treats that as an acceptable trade-off rather than a blocker: <em>“we would make [that trade-off] every time”</em> — get the smarter model and handle image recognition another way. A local router (they use OpenCode) sends image tasks to Gemini while GLM handles the main coding work. For teams that need vision directly, GLM’s Flash variant works well; their UI designer uses it and UI product turnaround improved substantially. All endpoints are OpenAI-compatible, which is what plugs into OpenCode, Codex and friends — compatibility is the feature he recommends optimizing for.</p>

<h2 id="the-compliance-answer-for-chinese-open-weights">The compliance answer for Chinese open weights</h2>

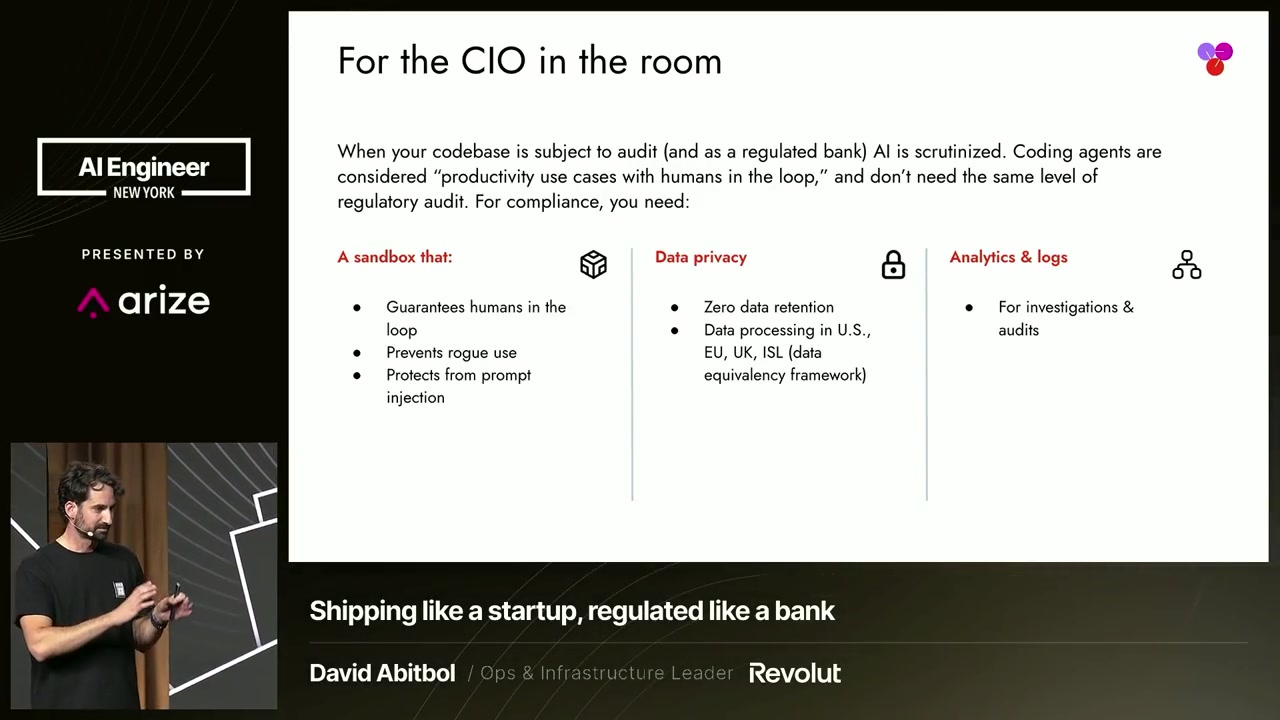
<p><img src="/assets/revolut-cio-sandbox.jpg" alt="For the CIO in the room: sandbox, data privacy, analytics" /></p>

<p>Revolut is an EU-regulated bank running Chinese open-weight models, and the argument to regulators is clean:</p>

<ul>
  <li><strong>Weights only, no inference to China.</strong> They download the weights and run them on US-based infrastructure — <em>“for data sharing side, this is totally fine.”</em></li>
  <li><strong>Coding agents are not autonomous agents.</strong> A human is always in the loop, and the sandbox is built to guarantee it: allow/deny rules per operation (allow <code class="language-plaintext highlighter-rouge">grep</code>, deny <code class="language-plaintext highlighter-rouge">gradle</code>, for instance). That classification — “productivity use case with humans in the loop” — is what keeps it out of the heaviest regulatory audit.</li>
  <li>The sandbox does double duty: it also shields against rogue internal use (<em>“you’d be surprised what you find in a large company”</em>) and prompt injection, which he considers less of a threat now that models are smarter, but still a live one.</li>
  <li><strong>Data privacy</strong>: GPUs can sit in any country in the data equivalency framework (US, EU, UK, Israel); GPU and inference providers have zero data retention by default.</li>
  <li><strong>Strong OpenTelemetry</strong> so any incident can be traced through deep logs.</li>
</ul>

<h2 id="the-through-line">The through-line</h2>

<p>The cost win and the compliance win come from the same discipline: <strong>constrain the system tightly</strong> — cap context, cap precision, cap permissions — instead of buying more capacity or a bigger model. The open question the talk leaves hanging is durability: these are one company’s internal numbers, the 1/10 cost figure assumes frontier API pricing holds, and nobody knows yet whether regulators will accept the human-in-the-loop sandbox argument as a general precedent or a Revolut-specific arrangement.</p>

<hr />

<p><em>Talk: <a href="https://www.youtube.com/watch?v=Ok6QdZHCcI8">How Revolut Cut AI Coding Costs 90% With Self-Hosted Open Models</a> — David Abitbol, Revolut @ AI Engineer. Slides captured from the video.</em></p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[I watched “How Revolut Cut AI Coding Costs 90% With Self-Hosted Open Models” — David Abitbol, who leads AI operations at Revolut, speaking at AI Engineer New York. His framing: “Shipping like a startup, regulated like a bank.” It is a dense technical talk, and almost every number in it is relevant to anyone running local models for agentic coding, so here are the points that matter.]]></summary></entry><entry><title type="html">The binary score hides the near-misses</title><link href="https://blog.veladan.org/2026/10/11/the-binary-score-hides-the-near-misses.html" rel="alternate" type="text/html" title="The binary score hides the near-misses" /><published>2026-10-11T00:00:00+00:00</published><updated>2026-10-11T00:00:00+00:00</updated><id>https://blog.veladan.org/2026/10/11/the-binary-score-hides-the-near-misses</id><content type="html" xml:base="https://blog.veladan.org/2026/10/11/the-binary-score-hides-the-near-misses.html"><![CDATA[<p>I <a href="https://x.com/danieltvela/status/2108975401741484092">posted this on X</a> after finishing two full runs of DeepSWE, and it turned into the most interesting question of the whole exercise, so here is the long version.</p>

<p>The published numbers place MiMo-v2.6-Flash above GLM-5.3-Flash (about 68% against about 63%). In daily use I would have sworn the opposite was true. So I ran the whole 113-task corpus against both, locally, same harness, same task order — and then looked at how the grading actually works.</p>

<h2 id="how-deepswe-scores">How DeepSWE scores</h2>

<p>Each of the 113 tasks is graded on a hidden test suite split in two. The <strong>fail-to-pass</strong> tests are the behavior the change is supposed to introduce. The <strong>pass-to-pass</strong> tests are the repository’s existing suite, which must not regress.</p>

<p>The score for a task is <code class="language-plaintext highlighter-rouge">1</code> if every f2p test passes and no p2p test fails. Otherwise it is <code class="language-plaintext highlighter-rouge">0</code>. The headline number — Pass@1 — is the share of tasks that scored 1.</p>

<p>That is a defensible definition of “did it ship”. It is also, as a summary of a model’s capability, throwing away almost everything the run measured.</p>

<h2 id="the-two-numbers-from-the-same-runs">The two numbers from the same runs</h2>

<p>Both of these come from my two local runs of the same 113 tasks:</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>GLM-5.3-Flash</th>
      <th>MiMo-V2.6-Flash-MOPD</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tasks resolved (official-style binary score)</td>
      <td>76/113 = <strong>67.3%</strong></td>
      <td>71/113 = <strong>62.8%</strong></td>
    </tr>
    <tr>
      <td>Target tests passed, pooled over the corpus</td>
      <td>5,723/5,877 = <strong>97.38%</strong></td>
      <td>5,555/5,877 = <strong>94.52%</strong></td>
    </tr>
    <tr>
      <td>Target tests passed, mean per task</td>
      <td>94.71%</td>
      <td>90.59%</td>
    </tr>
    <tr>
      <td>Tasks where <em>every</em> target test passed</td>
      <td>79</td>
      <td>74</td>
    </tr>
    <tr>
      <td>Tasks where 90–99% of target tests passed</td>
      <td><strong>25</strong></td>
      <td><strong>23</strong></td>
    </tr>
  </tbody>
</table>

<p>Two models, 113 tasks, and between them <strong>48 tasks where the model got between nine and ten out of every ten target tests right</strong> — and scored zero for it.</p>

<h2 id="why-that-is-structural-not-bad-luck">Why that is structural, not bad luck</h2>

<p>The tasks are not the same size. Not remotely:</p>

<p><img src="https://blog.veladan.org/assets/benchmarks/deepswe/f2p-suite-sizes.svg" alt="Target tests per task across the 113 DeepSWE tasks" /></p>

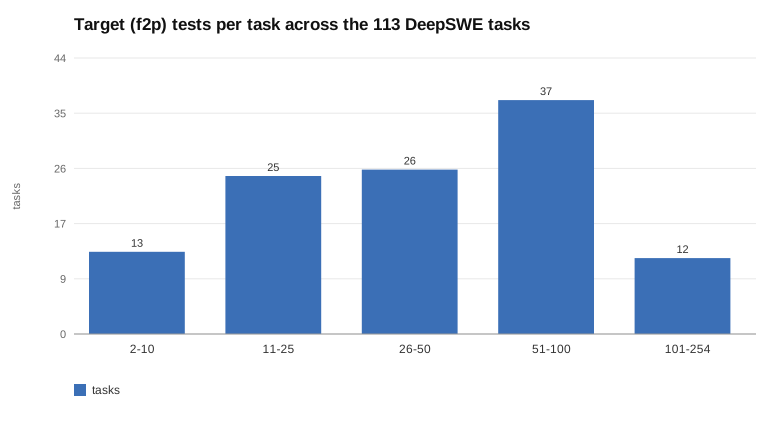
<p>The median task carries 44 target tests; the range runs from <strong>2 to 254</strong>. Thirteen tasks have ten target tests or fewer; twelve have a hundred or more. The regression suites are even more skewed — one task in the corpus has 66,265 of them, and the median is 165.</p>

<p>The binary rule gives every task the same weight — one point — regardless of how much behavior that task encodes. Three consequences follow, and all three showed up in my data:</p>

<p><strong>1. Failing one assertion and failing all of them are the same event.</strong> <code class="language-plaintext highlighter-rouge">kysely-window-grouping-helpers</code> has 254 target tests. A model that passes 253 of them scores zero, exactly like a model that passes none. I have 48 tasks in that neighborhood.</p>

<p><strong>2. A two-test task outranks a hundred-test task.</strong> <code class="language-plaintext highlighter-rouge">kgateway-consistent-hash-policy</code> has two target tests. Getting it wrong costs the same point as failing a task with 254. If the goal is to measure how much correct behavior a model produces, the ruler is not linear.</p>

<p><strong>3. The score is fragile to things that are not the model.</strong> Our local runs and the published numbers disagree about the ordering of these two models. Different weights (mine are 4-bit), a different serving stack, a different harness around the same agent framework. When a metric is a count of all-or-nothing events, a handful of tasks flipping moves the headline by percentage points — and a single task can flip for a reason as boring as a container that could not reach a package registry.</p>

<p><img src="https://blog.veladan.org/assets/benchmarks/deepswe/glm-f2p-bands.svg" alt="Tasks by share of target tests passed — GLM-5.3-Flash" /></p>

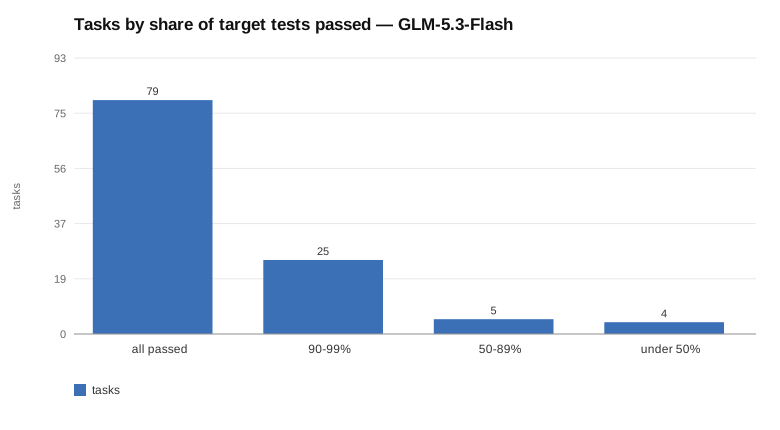
<p>That chart is the one I would put next to the leaderboard number. Seventy-nine tasks all-passed, twenty-five in the 90–99% band, five in 50–89%, four below half. The score says 67.3%. The distribution says “this model is almost always nearly right”.</p>

<h2 id="so-just-count-all-the-tests-then">So just count all the tests, then?</h2>

<p>Careful. Counting tests has its own trap, and the same corpus shows it.</p>

<p>The regression suites are extremely concentrated: the five largest tasks hold <strong>75.5%</strong> of all 231,352 p2p tests, and one task — <code class="language-plaintext highlighter-rouge">expr-try-catch-errors</code> — holds 66,265 of them, 38.7% of the corpus total. If a model broke that single task, our pooled p2p number would fall from 100.00% to about 61%, on the strength of one decision. Pooled p2p is not a measure of anything except a handful of giant test suites in the Go, Python and JavaScript corners of the corpus.</p>

<p>Target tests are better behaved (the top five f2p tasks hold 14% of the mass) but still uneven: pooling them means a 254-assertion task counts 127 times more than a 2-assertion one. That is at least <em>honest</em> weighting — it measures behavior covered, which is what it claims to measure — but it is a different question from “how many of these 113 tasks can the model finish”.</p>

<h2 id="what-i-would-report-instead">What I would report instead</h2>

<p>Reporting one number for a 113-task benchmark is a design choice, and the choice being made today is the harshest available. If I were presenting these runs, I would show four cheap things that the harness already records:</p>

<ol>
  <li><strong>Pass@1</strong> — the binary score, unchanged. It answers “did it ship”, and sometimes that is the only question.</li>
  <li><strong>Mean target-test coverage per task</strong> — <code class="language-plaintext highlighter-rouge">mean(f2p_passed / f2p_total)</code>. It answers “how close is a typical attempt”, and it is the number where GLM’s advantage over MiMo is largest (94.7% against 90.6%).</li>
  <li><strong>The band distribution</strong> — all-passed / 90–99% / 50–89% / under 50%. It is one chart, it costs nothing, and it exposes exactly what the pass rate hides.</li>
  <li><strong>Regression failures as a count, per task</strong> — “broke existing behavior on 5 tasks”, not a pooled percentage that five giant suites dominate.</li>
</ol>

<p>None of this replaces the binary metric. It contextualizes it. A model with 67% Pass@1 and 25 near-misses is a different instrument from a model with 67% Pass@1 and 25 catastrophic failures, and a reader choosing a model deserves to know which one they are looking at.</p>

<h2 id="the-honest-counter-argument">The honest counter-argument</h2>

<p>Partial credit can flatter a patch that is wrong where it matters. A change that passes 253 of 254 target tests may be failing precisely the assertion that encodes the security check, or the edge case the whole task was written to test. The corpus authors chose all-or-nothing because “mostly working” is not a category you can ship, and on that basis the metric is doing what it says.</p>

<p>My claim is narrower than “the metric is wrong”. It is that the metric is <strong>incomplete as a headline</strong> — it collapses a graded outcome into a coin flip per task, it ignores how much behavior each task contains, and it makes the published ranking sensitive to configuration details that no reader can see. The information needed to fix that is already being collected by the harness; it just is not being shown.</p>

<h2 id="what-this-does-not-prove">What this does not prove</h2>

<ul>
  <li>113 tasks, one run each. The confidence intervals are wide (76/113 gives [58.2, 75.2]) and I have not done repetitions.</li>
  <li>My local runs use quantized weights on consumer cards. The published numbers come from other configurations entirely, and part of what I am calling “fragility” could just be my quantization.</li>
  <li>Test counts are a proxy for behavior, not a measure of importance. A two-assertion task can encode the only thing that matters.</li>
  <li>Two models is not a trend. I have four models on the five Rust tasks and two on the full corpus; the pattern is consistent, but it is two data points.</li>
</ul>

<h2 id="reproducibility">Reproducibility</h2>

<p>Every number above comes from the run records: one JSON file per batch, one entry per trial, with the f2p and p2p tallies the verifier produced. The audit that checks the verifier logs for environment failures (and that caught a false 0/62 in a different model’s run) is a <code class="language-plaintext highlighter-rouge">grep</code> over those logs. The charts are generated from the same records.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[I posted this on X after finishing two full runs of DeepSWE, and it turned into the most interesting question of the whole exercise, so here is the long version.]]></summary></entry><entry><title type="html">MiMo-V2.6-Flash on DeepSWE: 71 of 113 tasks, done in 90 steps per task</title><link href="https://blog.veladan.org/2026/10/10/mimo-v2-6-flash-deepswe-113-tasks.html" rel="alternate" type="text/html" title="MiMo-V2.6-Flash on DeepSWE: 71 of 113 tasks, done in 90 steps per task" /><published>2026-10-10T23:30:00+00:00</published><updated>2026-10-10T23:30:00+00:00</updated><id>https://blog.veladan.org/2026/10/10/mimo-v2-6-flash-deepswe-113-tasks</id><content type="html" xml:base="https://blog.veladan.org/2026/10/10/mimo-v2-6-flash-deepswe-113-tasks.html"><![CDATA[<p>This is the companion run to the GLM-5.3-Flash evaluation: same 113 tasks, same agent framework, same fixed task order, same binary grading. MiMo-V2.6-Flash-MOPD came out of it with <strong>71 of 113 tasks resolved (62.8%)</strong> and <strong>94.52% of all target tests passing</strong>, using markedly less effort per task than GLM — and failing in a way that is genuinely different.</p>

<h2 id="the-setup">The setup</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th> </th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Model</td>
      <td>MiMo-V2.6-Flash-MOPD (Xiaomi), W4A8 (MXFP4 experts + FP8 dense)</td>
    </tr>
    <tr>
      <td>Server</td>
      <td>vLLM, tensor parallel 2 (2x RTX PRO 6000 Blackwell Max-Q)</td>
    </tr>
    <tr>
      <td>Context</td>
      <td>448,512 tokens, KV cache in fp8, DFlash speculative decoding</td>
    </tr>
    <tr>
      <td>Agent</td>
      <td>mini-swe-agent, <code class="language-plaintext highlighter-rouge">model_class: litellm</code>, one task at a time</td>
    </tr>
    <tr>
      <td>Per-task time budget</td>
      <td>180 minutes, the corpus’s own limit</td>
    </tr>
    <tr>
      <td>Task order</td>
      <td>Fixed seed, identical to the GLM run</td>
    </tr>
  </tbody>
</table>

<p>Everything was served locally and quantized; the official board number for this model (about 68%) comes from a different setup with different weights, and I am not claiming to reproduce it.</p>

<h2 id="the-result">The result</h2>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tasks resolved</td>
      <td><strong>71 / 113 (62.8%)</strong>, 95% CI [53.6 – 71.2]</td>
    </tr>
    <tr>
      <td>Target tests passed (pooled)</td>
      <td>5,555 / 5,877 = <strong>94.52%</strong></td>
    </tr>
    <tr>
      <td>Target tests passed (mean per task)</td>
      <td>90.59%</td>
    </tr>
    <tr>
      <td>Regression tests passed (pooled)</td>
      <td>231,316 / 231,352 = <strong>99.984%</strong> (36 failures)</td>
    </tr>
    <tr>
      <td>Regression tests passed (mean per task)</td>
      <td>99.86%</td>
    </tr>
    <tr>
      <td>Time per task</td>
      <td>median 15.8 min, mean 18.1 min, max 46.3 min</td>
    </tr>
    <tr>
      <td>Time spent</td>
      <td>31.4 h of agent time, 34.0 h of wall time</td>
    </tr>
    <tr>
      <td>Effort</td>
      <td>10,190 steps (<strong>90 per task</strong>), far fewer than GLM’s 139</td>
    </tr>
  </tbody>
</table>

<p>The maximum is worth a sentence of its own: <strong>the longest task took 46 minutes</strong>, well under the corpus’s three-hour ceiling. Whatever else this model does, it does not sprawl. It reached the same wall-clock average as GLM (18.1 vs 19.0 minutes per task) with about a third fewer steps, which says its steps are longer — more reasoning or more generation packed into each turn.</p>

<h2 id="where-the-tasks-land">Where the tasks land</h2>

<p><img src="https://blog.veladan.org/assets/benchmarks/deepswe/mimo-f2p-bands.svg" alt="Tasks by share of target tests passed" /></p>

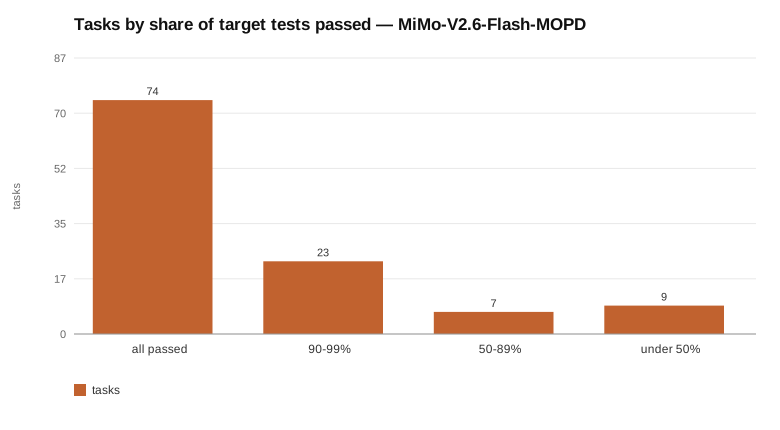
<p>The shape is similar to GLM’s — most tasks either pass everything or land in the 90–99% band — but the tail is heavier. MiMo has <strong>9 tasks below 50% of their target tests</strong>, against 4 for GLM, and 7 in the 50–89% band. When this model misses, it misses further.</p>

<h2 id="by-language">By language</h2>

<table>
  <thead>
    <tr>
      <th>Language</th>
      <th>Resolved</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Go</td>
      <td><strong>26/35</strong></td>
    </tr>
    <tr>
      <td>Python</td>
      <td>21/34</td>
    </tr>
    <tr>
      <td>TypeScript</td>
      <td>20/34</td>
    </tr>
    <tr>
      <td>Rust</td>
      <td>1/5</td>
    </tr>
    <tr>
      <td>JavaScript</td>
      <td><strong>3/5</strong></td>
    </tr>
  </tbody>
</table>

<p>Go and JavaScript are where MiMo beats GLM by one task each. Python and TypeScript are where it loses ground, and Rust is a rout in the other direction: MiMo resolved one of the five Rust tasks, GLM resolved three.</p>

<h2 id="where-it-earns-its-keep">Where it earns its keep</h2>

<p>Fourteen tasks were solved by MiMo and by nothing else in this comparison: <code class="language-plaintext highlighter-rouge">awilix-async-container-initialization</code>, <code class="language-plaintext highlighter-rouge">bandit-interprocedural-taint-checks</code>, <code class="language-plaintext highlighter-rouge">go-git-worktree-merge-conflicts</code>, <code class="language-plaintext highlighter-rouge">happy-dom-deterministic-intersectionobserver</code>, <code class="language-plaintext highlighter-rouge">ipython-session-bundle-replay</code>, <code class="language-plaintext highlighter-rouge">koota-pair-relation-tracking</code>, <code class="language-plaintext highlighter-rouge">mashumaro-flattened-dataclass-fields</code>, <code class="language-plaintext highlighter-rouge">onedump-dump-encryption-pipeline</code>, <code class="language-plaintext highlighter-rouge">prometheus-typed-label-sorting</code>, <code class="language-plaintext highlighter-rouge">scc-bounded-memory-spilling</code>, <code class="language-plaintext highlighter-rouge">superjson-error-stack-serialization</code>, <code class="language-plaintext highlighter-rouge">tengo-callable-instance-isolation</code>, <code class="language-plaintext highlighter-rouge">testem-per-launcher-reports</code> and <code class="language-plaintext highlighter-rouge">updo-policy-alerting</code>.</p>

<p><code class="language-plaintext highlighter-rouge">mashumaro-flattened-dataclass-fields</code> is the cleanest example: MiMo scored 66/66 on the target tests, GLM scored 63/66. Three assertions, one point, and the two models are on opposite sides of the line. That is the sharpest illustration I have of how much the binary metric compresses.</p>

<h2 id="its-failure-modes">Its failure modes</h2>

<p>Of the 42 failures:</p>

<ul>
  <li><strong>23 near-misses</strong> in the 90–99% band.</li>
  <li><strong>3 tasks with every target test passing and a regression costing the point</strong>: <code class="language-plaintext highlighter-rouge">bandit-structured-nosec-directives</code>, <code class="language-plaintext highlighter-rouge">kombu-single-active-consumer-priority</code> and <code class="language-plaintext highlighter-rouge">vulture-persistent-analysis-cache</code> — the last one is also in GLM’s list, so two different models broke the same existing behavior on the same task.</li>
  <li><strong>7 in the 50–89% band</strong> and <strong>9 below 50%</strong>, the tail I mentioned above.</li>
</ul>

<h2 id="mimo-against-glm-on-the-same-113-tasks">MiMo against GLM, on the same 113 tasks</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>MiMo-V2.6-Flash-MOPD</th>
      <th>GLM-5.3-Flash</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Resolved</td>
      <td>71/113 (62.8%)</td>
      <td><strong>76/113 (67.3%)</strong></td>
    </tr>
    <tr>
      <td>Pooled target tests</td>
      <td>94.52%</td>
      <td><strong>97.38%</strong></td>
    </tr>
    <tr>
      <td>Mean per task</td>
      <td>90.59%</td>
      <td><strong>94.71%</strong></td>
    </tr>
    <tr>
      <td>Pooled regression tests</td>
      <td>99.984% (36 broken)</td>
      <td><strong>99.993% (17 broken)</strong></td>
    </tr>
    <tr>
      <td>Steps per task</td>
      <td><strong>90</strong></td>
      <td>139</td>
    </tr>
    <tr>
      <td>Longest task</td>
      <td><strong>46 min</strong></td>
      <td>79 min</td>
    </tr>
    <tr>
      <td>Tasks under 50% of target tests</td>
      <td>9</td>
      <td><strong>4</strong></td>
    </tr>
  </tbody>
</table>

<p>GLM resolves more and gets closer on what it does not resolve; MiMo works more cheaply and has a narrower tail of catastrophic misses. Both statements are true at once, which is exactly the messiness the single pass-rate number hides — and the subject of the next post.</p>

<h2 id="what-this-does-not-prove">What this does not prove</h2>

<ul>
  <li><strong>One run per task</strong>, so the interval on 71/113 is [53.6, 71.2].</li>
  <li><strong>Quantized weights and a locally served endpoint</strong>, not the configuration behind the published number.</li>
  <li><strong>Five Rust tasks.</strong> The 1/5 here and the 3/5 for GLM are small-sample observations, not a ranking of the models on Rust.</li>
</ul>

<h2 id="reproducibility">Reproducibility</h2>

<p>The run is driven by the same <code class="language-plaintext highlighter-rouge">eval/</code> tooling described in the GLM post: a model registry entry with the serving metadata, a scheduler that survives being stopped, and one JSON record per batch plus a full agent trajectory and verifier log per trial. All 113 verifier logs for this model were audited for environment failures (network errors during dependency fetch, or a verifier that failed in both the base and new mode) and came back clean.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[This is the companion run to the GLM-5.3-Flash evaluation: same 113 tasks, same agent framework, same fixed task order, same binary grading. MiMo-V2.6-Flash-MOPD came out of it with 71 of 113 tasks resolved (62.8%) and 94.52% of all target tests passing, using markedly less effort per task than GLM — and failing in a way that is genuinely different.]]></summary></entry><entry><title type="html">GLM-5.3-Flash on DeepSWE: 76 of 113 tasks, and 25 more that were one test short</title><link href="https://blog.veladan.org/2026/10/10/glm-5-3-flash-deepswe-113-tasks.html" rel="alternate" type="text/html" title="GLM-5.3-Flash on DeepSWE: 76 of 113 tasks, and 25 more that were one test short" /><published>2026-10-10T23:00:00+00:00</published><updated>2026-10-10T23:00:00+00:00</updated><id>https://blog.veladan.org/2026/10/10/glm-5-3-flash-deepswe-113-tasks</id><content type="html" xml:base="https://blog.veladan.org/2026/10/10/glm-5-3-flash-deepswe-113-tasks.html"><![CDATA[<p>I ran the whole DeepSWE v1.1 corpus against GLM-5.3-Flash, quantized to four bits and served locally on two consumer Blackwell cards. Not a subset, not a smoke test: all 113 tasks, one at a time, each with the benchmark’s own hidden test suite grading the result. This is what came out.</p>

<p>Short version: <strong>76 of 113 tasks resolved (67.3%)</strong>, <strong>97.38% of all target tests passing</strong>, and 17 broken tests out of 231,352 regression tests. The number I keep coming back to is different though: 25 tasks scored zero while passing 90–99% of their target tests.</p>

<h2 id="what-the-benchmark-is-and-how-it-grades">What the benchmark is, and how it grades</h2>

<p>DeepSWE v1.1 is a corpus of 113 tasks, each derived from a real pull request in a real repository: a base commit, an instruction, and a hidden test suite. The suite splits in two. The <strong>fail-to-pass (f2p)</strong> tests are the ones the change is supposed to make pass; the <strong>pass-to-pass (p2p)</strong> tests are the repository’s existing tests, which must keep passing.</p>

<p>The grading is binary per task: <strong>a task scores 1 only if every f2p test passes and no p2p test fails</strong>. Anything else is a zero. There is a partial metric in the harness, but it is p2p-dominated and I will not use it; what I report below is the binary pass rate plus the graded share of target tests, which I compute myself.</p>

<p>The agent sees only the instruction and the repository at the base commit. The tests live in a separate container that the agent never touches, and the agent runs with no network access. It cannot see what it is being scored on.</p>

<h2 id="the-setup">The setup</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th> </th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Model</td>
      <td>GLM-5.3-Flash (Zhipu AI), W4A16 NVFP4 experts + FP8 weights</td>
    </tr>
    <tr>
      <td>Server</td>
      <td>SGLang, tensor parallel 2 (2x RTX PRO 6000 Blackwell Max-Q)</td>
    </tr>
    <tr>
      <td>Context</td>
      <td>524,288 tokens, KV cache in fp8, EAGLE speculative decoding</td>
    </tr>
    <tr>
      <td>Agent</td>
      <td>mini-swe-agent, <code class="language-plaintext highlighter-rouge">model_class: litellm</code>, one task at a time</td>
    </tr>
    <tr>
      <td>Per-task time budget</td>
      <td>180 minutes, the corpus’s own <code class="language-plaintext highlighter-rouge">[agent] timeout_sec</code></td>
    </tr>
    <tr>
      <td>Task order</td>
      <td>Fixed seed, identical to the run I did with MiMo, so comparisons are task by task</td>
    </tr>
  </tbody>
</table>

<p>Everything ran unattended across four nights, resuming from a state file after each interruption. Wall clock is not the interesting part; I mention it because a 113-task run only becomes practical if it survives being stopped.</p>

<h2 id="the-result">The result</h2>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tasks resolved</td>
      <td><strong>76 / 113 (67.3%)</strong>, 95% CI [58.2 – 75.2]</td>
    </tr>
    <tr>
      <td>Target tests passed (pooled)</td>
      <td>5,723 / 5,877 = <strong>97.38%</strong></td>
    </tr>
    <tr>
      <td>Target tests passed (mean per task)</td>
      <td>94.71%</td>
    </tr>
    <tr>
      <td>Regression tests passed (pooled)</td>
      <td>231,335 / 231,352 = <strong>99.993%</strong> (17 failures)</td>
    </tr>
    <tr>
      <td>Regression tests passed (mean per task)</td>
      <td>99.74%</td>
    </tr>
    <tr>
      <td>Time per task</td>
      <td>median 16.3 min, mean 19.0 min, max 78.6 min</td>
    </tr>
    <tr>
      <td>Time spent</td>
      <td>32.9 h of agent time, 35.8 h of wall time</td>
    </tr>
    <tr>
      <td>Effort</td>
      <td>15,654 steps (139 per task), ~99k output tokens per task, 64% of them reasoning</td>
    </tr>
  </tbody>
</table>

<p>Two ways of aggregating appear above on purpose. Pooled means “of all the target tests in the corpus, what share passed”; the per-task mean means “in a typical task, what share of its tests passed”. They differ because the tasks are wildly unequal in size — from 2 to 254 target tests — and I will come back to that in a later post, because it is the most interesting thing I found in this whole exercise.</p>

<h2 id="where-the-tasks-land">Where the tasks land</h2>

<p><img src="https://blog.veladan.org/assets/benchmarks/deepswe/glm-f2p-bands.svg" alt="Tasks by share of target tests passed" /></p>

<p>Read the second bar. <strong>Twenty-five tasks passed 90–99% of their target tests and scored zero.</strong> They are not failures in any useful sense of the word: they are changes that got one edge case wrong, or left one branch untested, out of suites that often contain more than a hundred assertions.</p>

<p>The other end is thin: only 4 tasks ended below 50% of their target tests. This is not a model that collapses on hard work; it is a model that consistently gets most of the way and then misses a detail.</p>

<h2 id="by-language">By language</h2>

<table>
  <thead>
    <tr>
      <th>Language</th>
      <th>Resolved</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Go</td>
      <td>25/35</td>
      <td>the largest group; failures spread thin</td>
    </tr>
    <tr>
      <td>Python</td>
      <td>25/34</td>
      <td> </td>
    </tr>
    <tr>
      <td>TypeScript</td>
      <td>21/34</td>
      <td> </td>
    </tr>
    <tr>
      <td>Rust</td>
      <td>3/5</td>
      <td>all five Rust tasks are in the corpus</td>
    </tr>
    <tr>
      <td>JavaScript</td>
      <td>2/5</td>
      <td> </td>
    </tr>
  </tbody>
</table>

<p>Rust is the group I care about most and the group the benchmark covers least — five tasks is a sample, not a verdict. On those five, GLM resolved three, a better rate than any other model I have run locally.</p>

<h2 id="three-ways-to-lose-a-point">Three ways to lose a point</h2>

<p>The 37 failures break down into three distinct stories, and only one of them is a real “the model could not do this” story.</p>

<p><strong>Three tasks where every target test passed and a regression cost the point.</strong> <code class="language-plaintext highlighter-rouge">gql-incremental-graphql-delivery</code> scored 17/17 on target tests and 810/811 on regression; <code class="language-plaintext highlighter-rouge">helm-array-merge-strategies</code> scored 47/47 and 10/12; <code class="language-plaintext highlighter-rouge">vulture-persistent-analysis-cache</code> scored 24/24 and 291/295. The feature is implemented; something that used to work stopped working. If I were shipping this code I would want exactly that information, and the binary metric does convey it — but it conveys it identically to a task where nothing works at all.</p>

<p><strong>Twenty-five near-misses</strong> in the 90–99% band, plus five more in the 50–89% band.</p>

<p><strong>Four genuinely far off</strong>: <code class="language-plaintext highlighter-rouge">boa-hierarchical-evaluation-cancellation</code> (0/17 target tests), <code class="language-plaintext highlighter-rouge">eicrud-keyset-pagination-cursor</code>, <code class="language-plaintext highlighter-rouge">kgateway-consistent-hash-policy</code> (0/2) and <code class="language-plaintext highlighter-rouge">onedump-dump-encryption-pipeline</code>. For what it is worth, MiMo fails the first two as well.</p>

<h2 id="what-i-take-from-it">What I take from it</h2>

<p>GLM-5.3-Flash is a <em>mostly right</em> model, and DeepSWE’s binary metric punishes exactly that shape. Ninety-seven percent of all the target tests in the corpus pass; more than two thirds of the tasks are resolved outright; and a quarter of the corpus sits one test away from being counted. If your question is “can this model do the work”, the pooled number is the honest answer. If your question is “will it ship without a regression”, the binary number is the honest answer, and it is 67.3%.</p>

<p>The one weakness I would flag for real use: GLM’s failures concentrate in regressions on existing behavior rather than in the requested behavior. That is the kind of error a code review catches and a test suite catches better.</p>

<h2 id="what-this-does-not-prove">What this does not prove</h2>

<ul>
  <li><strong>One run per task.</strong> No repetitions. The 95% confidence interval on 76/113 is [58.2, 75.2] — wide, because 113 binary outcomes carry only so much information.</li>
  <li><strong>Quantized weights.</strong> This is a 4-bit build (NVFP4 experts, FP8 weights), not the full-precision model the official leaderboard measured at ~63%. Quantization is part of the result, not a footnote to it.</li>
  <li><strong>My harness is not the official one.</strong> Same corpus, same grading container, same agent framework, but my own driver, my own serving stack, and locally served weights. Numbers will differ from the board’s, which for GLM-5.3-Flash is around 63%.</li>
  <li><strong>Rust is five tasks.</strong> Anything I say about Rust is a five-task observation.</li>
</ul>

<h2 id="reproducibility">Reproducibility</h2>

<p>The run lives in a fork of the DeepSWE repository with an <code class="language-plaintext highlighter-rouge">eval/</code> directory that drives it: <code class="language-plaintext highlighter-rouge">eval/models.yaml</code> for the model registry (identity, quantization, serving metadata), <code class="language-plaintext highlighter-rouge">eval/nightly.py</code> for the scheduler, and a results tree with one JSON record per batch. Every trial keeps its own container logs, the agent’s full trajectory, and the verifier output, so a number can be traced back to the run that produced it. All 113 verifier logs for this model were audited for environment failures — network errors during the build, or a verifier that failed in both the base and the new mode — and none were found.</p>

<p>The aggregate report is an HTML page generated from those records; the numbers above come from it, cross-checked against the raw trial files.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[I ran the whole DeepSWE v1.1 corpus against GLM-5.3-Flash, quantized to four bits and served locally on two consumer Blackwell cards. Not a subset, not a smoke test: all 113 tasks, one at a time, each with the benchmark’s own hidden test suite grading the result. This is what came out.]]></summary></entry><entry><title type="html">Four local models, five Rust tasks: a per-task comparison</title><link href="https://blog.veladan.org/2026/10/10/four-local-models-five-rust-tasks.html" rel="alternate" type="text/html" title="Four local models, five Rust tasks: a per-task comparison" /><published>2026-10-10T17:00:00+00:00</published><updated>2026-10-10T17:00:00+00:00</updated><id>https://blog.veladan.org/2026/10/10/four-local-models-five-rust-tasks</id><content type="html" xml:base="https://blog.veladan.org/2026/10/10/four-local-models-five-rust-tasks.html"><![CDATA[<p>DeepSWE covers five languages, and Rust is the smallest slice of it: five tasks out of 113. That makes it a bad sample and an irresistible one — Rust is what I actually care about, compiling is where verification gets expensive, and five tasks are few enough to compare four models task by task instead of by average.</p>

<p>So that is what this is. The same five tasks, four locally served models, the same agent framework, the same grading container, one run each. Not a leaderboard; a close reading.</p>

<h2 id="the-four-models">The four models</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>MiMo-V2.6-Flash-MOPD</th>
      <th>GLM-5.3-Flash</th>
      <th>Qwen3.8-Flash-Next</th>
      <th>Laguna-S-2.1</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Lab</td>
      <td>Xiaomi</td>
      <td>Zhipu AI</td>
      <td>Alibaba</td>
      <td>Poolside</td>
    </tr>
    <tr>
      <td>Quantization</td>
      <td>W4A8</td>
      <td>W4A16 NVFP4 + FP8 WO</td>
      <td>NVFP4</td>
      <td>NVFP4</td>
    </tr>
    <tr>
      <td>Server</td>
      <td>vLLM</td>
      <td>SGLang</td>
      <td>vLLM</td>
      <td>vLLM</td>
    </tr>
    <tr>
      <td>Context</td>
      <td>448,512</td>
      <td>524,288</td>
      <td><strong>262,144</strong></td>
      <td><strong>1,048,576</strong></td>
    </tr>
    <tr>
      <td>Tensor parallel</td>
      <td>2</td>
      <td>2</td>
      <td><strong>1</strong></td>
      <td>2</td>
    </tr>
  </tbody>
</table>

<p>All four ran on the same two RTX PRO 6000 Blackwell cards, one model at a time, because a locally served model owns both GPUs. Qwen is the odd one out twice over: the shortest context window by a factor of two, and the only one that fits on a single card.</p>

<h2 id="the-five-tasks">The five tasks</h2>

<p>Straight from the corpus: <code class="language-plaintext highlighter-rouge">boa-hierarchical-evaluation-cancellation</code> (the Boa JavaScript engine), <code class="language-plaintext highlighter-rouge">fd-deterministic-multi-key-sorting</code> (the fd file finder), <code class="language-plaintext highlighter-rouge">oxvg-structural-selector-preservation</code> (an SVG optimizer), <code class="language-plaintext highlighter-rouge">pest-character-class-coalescing</code> (the pest parser generator) and <code class="language-plaintext highlighter-rouge">wasmi-trap-coredumps</code> (the wasmi WebAssembly interpreter).</p>

<table>
  <thead>
    <tr>
      <th>Task</th>
      <th>MiMo</th>
      <th>GLM</th>
      <th>Qwen</th>
      <th>Laguna</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">boa-hierarchical-evaluation-cancellation</code></td>
      <td>0/17</td>
      <td>0/17</td>
      <td>0/17</td>
      <td>0/17</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">fd-deterministic-multi-key-sorting</code></td>
      <td><strong>43/43 ✓</strong></td>
      <td><strong>43/43 ✓</strong></td>
      <td><strong>43/43 ✓</strong></td>
      <td>42/43</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">oxvg-structural-selector-preservation</code></td>
      <td>4/6</td>
      <td>4/6</td>
      <td><strong>6/6 ✓</strong></td>
      <td>6/6 (p2p 60/62)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">pest-character-class-coalescing</code></td>
      <td>100/104</td>
      <td><strong>104/104 ✓</strong></td>
      <td>102/104</td>
      <td>82/104</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">wasmi-trap-coredumps</code></td>
      <td>20/22</td>
      <td><strong>22/22 ✓</strong></td>
      <td>0/22</td>
      <td>8/22</td>
    </tr>
  </tbody>
</table>

<p>✓ marks a resolved task: every target test passing and no regression. Numbers are target tests passed out of the suite size.</p>

<p><img src="https://blog.veladan.org/assets/benchmarks/deepswe/rust-four-models.svg" alt="Share of target tests passed across the five Rust tasks, for four local models" /></p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Resolved</th>
      <th>Target tests (mean per task)</th>
      <th>Regression tests</th>
      <th>Total time</th>
      <th>Steps per task</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>GLM-5.3-Flash</td>
      <td><strong>3/5</strong></td>
      <td>73.3%</td>
      <td>100.00%</td>
      <td>2.71 h</td>
      <td>246</td>
    </tr>
    <tr>
      <td>Qwen3.8-Flash-Next</td>
      <td>2/5</td>
      <td>59.6%</td>
      <td>99.92%</td>
      <td><strong>1.57 h</strong></td>
      <td>142</td>
    </tr>
    <tr>
      <td>MiMo-V2.6-Flash-MOPD</td>
      <td>1/5</td>
      <td>70.7%</td>
      <td>99.92%</td>
      <td>1.86 h</td>
      <td>129</td>
    </tr>
    <tr>
      <td>Laguna-S-2.1</td>
      <td>0/5</td>
      <td>62.6%</td>
      <td>99.27%</td>
      <td>3.03 h</td>
      <td><strong>365</strong></td>
    </tr>
  </tbody>
</table>

<h2 id="four-stories-one-per-task">Four stories, one per task</h2>

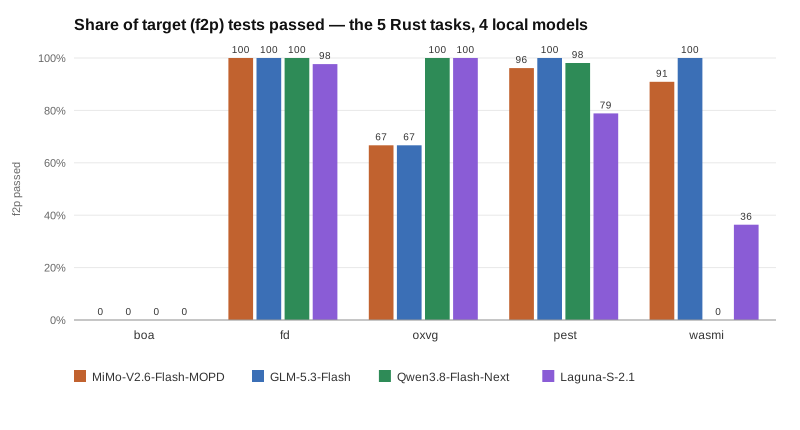
<p><strong><code class="language-plaintext highlighter-rouge">boa</code> is the wall.</strong> None of the four models passed a single one of its 17 target tests, and none of them broke anything either (7/7 regression tests, all four). This is the task that tells me the suite in this corpus is not decorative: it is a change inside a JavaScript engine’s evaluation machinery, and every local model I have tried bounces off it.</p>

<p><strong><code class="language-plaintext highlighter-rouge">fd</code> is the floor.</strong> All four models implemented deterministic multi-key sorting in the file finder. Laguna came within one assertion (42/43); the other three were perfect. If a task in this group is going to be solved, it is this one — and the interesting signal is not the score but the cost: MiMo took 11 minutes and GLM 11 minutes, Qwen 13, Laguna 19.</p>

<p><strong><code class="language-plaintext highlighter-rouge">oxvg</code> is the discriminator.</strong> Qwen and Laguna implemented all six target behaviors; MiMo and GLM stopped at four. But the two that “solved” it did not get the same result — Laguna’s patch passed 6/6 target tests and broke two existing ones (60/62), so it scores zero. This is the cleanest example in the whole comparison of a model doing the requested work and losing the point on a regression.</p>

<p><strong><code class="language-plaintext highlighter-rouge">wasmi</code> is where effort and context collide.</strong> GLM resolved it (22/22) in 26 minutes. MiMo got 20/22. Laguna got 8/22. And Qwen did not get evaluated at all: its agent’s prompt reached <strong>263,213 tokens against a 262,144-token window</strong>, the call failed with a context-length error, the agent exited before committing, and the harness collected an empty patch. The verifier then graded the pristine repository and reported 0/22 — which the binary metric duly recorded as a failure, indistinguishable from a model that never understood the task.</p>

<p>That last one deserves the emphasis. With a 448k or 524k window, MiMo’s and GLM’s own peak contexts on this task (326,215 and 339,270 tokens) would have overflowed Qwen’s window too. The 0/22 is a property of the serving configuration as much as of the model, and nothing in the score says so.</p>

<h2 id="the-verifier-that-lied">The verifier that lied</h2>

<p>Laguna’s first pass on <code class="language-plaintext highlighter-rouge">oxvg</code> came back as <strong>0/6 target tests and 0/62 regression tests</strong> — a catastrophic result that, on inspection, had nothing to do with the model. The verifier log showed both the base run and the new run failing with <code class="language-plaintext highlighter-rouge">rc=102</code> and 64 lines of <code class="language-plaintext highlighter-rouge">Could not resolve host: static.crates.io</code>: the verification container could not download Rust dependencies, so it never compiled the pristine repository either, and with no JUnit output the harness counts every test as failed.</p>

<p>The task was re-queued and re-run. The second pass had a healthy verifier and produced the 6/6 with two regressions reported above. The difference between the two results is not a model difference; it is a network difference.</p>

<p>That cost me an afternoon, so I turned it into a routine: every verifier log in a run is scanned for exactly this pattern — network failures, or a build that failed in both modes. Across all the runs in this project (194 verifier logs: 113 MiMo, 71 GLM at the time, 5 Qwen, 5 Laguna), <strong>exactly one was invalid</strong>, and it is the one above. The check is a <code class="language-plaintext highlighter-rouge">grep</code>, which is the right price for not publishing a fake zero.</p>

<h2 id="what-i-take-from-five-tasks">What I take from five tasks</h2>

<ul>
  <li><strong>Ownership is per task, not per model.</strong> Each of the five has a different answer: one nobody solves, one everybody solves, one only Qwen and Laguna touch, one only GLM, one only GLM with everyone else failing differently. Averaging these into a single “Rust score” throws away the only interesting part.</li>
  <li><strong>Context length is a functional parameter, not a spec sheet number.</strong> The cheapest model in this group to run was also the only one whose run was cut short by its own window.</li>
  <li><strong>The measurement instrument needs auditing as much as the thing being measured.</strong> A verification container that cannot reach a package registry produces zeros that look exactly like failures.</li>
  <li><strong>Compiled languages are where the harness gets expensive.</strong> These five tasks took 1.6 to 3.0 hours each in total, and Rust verification means compiling a repository twice (base and patched) per task. That cost is why this group has five tasks and not fifty.</li>
</ul>

<h2 id="what-this-does-not-prove">What this does not prove</h2>

<p>Five tasks, one run each, four models. The confidence intervals on 3/5, 2/5, 1/5 and 0/5 are enormous and overlapping. Two of the four models (Qwen, Laguna) have been run on Rust only, so nothing here says anything about how they behave on the other 108 tasks. Treat this as a case study of four specific models on five specific changes, not as a ranking.</p>

<h2 id="reproducibility">Reproducibility</h2>

<p>Each model has its own state file and its own run records; the Rust subset was selected by language from the same corpus manifest that drives the full runs, in the same seeded order, so the task-by-task comparison is exact. Every trial keeps the agent’s full trajectory, the container logs and the verifier output, including the failed first pass of <code class="language-plaintext highlighter-rouge">oxvg</code> for Laguna, which is where the <code class="language-plaintext highlighter-rouge">static.crates.io</code> evidence lives.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[DeepSWE covers five languages, and Rust is the smallest slice of it: five tasks out of 113. That makes it a bad sample and an irresistible one — Rust is what I actually care about, compiling is where verification gets expensive, and five tasks are few enough to compare four models task by task instead of by average.]]></summary></entry><entry><title type="html">The Model Still Wins: A Black-Box Benchmark of a Tuned Harness vs a Stronger Model</title><link href="https://blog.veladan.org/2026/10/02/model-still-wins-harness-vs-model.html" rel="alternate" type="text/html" title="The Model Still Wins: A Black-Box Benchmark of a Tuned Harness vs a Stronger Model" /><published>2026-10-02T00:00:00+00:00</published><updated>2026-10-02T00:00:00+00:00</updated><id>https://blog.veladan.org/2026/10/02/model-still-wins-harness-vs-model</id><content type="html" xml:base="https://blog.veladan.org/2026/10/02/model-still-wins-harness-vs-model.html"><![CDATA[<p>Everyone building agent tooling shares a quiet hope: that enough instructions, skills and custom tools can compensate for a weaker model. I wanted to test that hope instead of assuming it. So I built a small, deliberately boring benchmark: two complete agent stacks, one task, one frozen contract, and a hidden test suite that neither stack could see. The result surprised me less than the <em>shape</em> of the failures.</p>

<p>Short version: the stronger model on the plain harness scored 47/50 (94%) in 23 minutes; the weaker model on the fully tuned harness scored 38/50 (76%) in 11m46s. The harness nearly doubled the throughput of the weaker stack — and did not buy a single error-path behavior.</p>

<h2 id="the-task-a-contract-you-cannot-argue-with">The task: a contract you cannot argue with</h2>

<p>The task is a Vapor 4 REST API in Swift, on Linux, with no Xcode: a small library-lending service called <em>shelf</em>. Users register and log in (JWT HS256, 3600 s tokens), admins manage books, members borrow and return them, fines accrue at 50 cents per overdue day, and all state lives in a single SQLite file. The prompt specifies the exact HTTP contract: endpoints, status codes, JSON shapes, ten stable error codes (<code class="language-plaintext highlighter-rouge">validation_failed</code>, <code class="language-plaintext highlighter-rouge">email_taken</code>, <code class="language-plaintext highlighter-rouge">no_copies</code>, <code class="language-plaintext highlighter-rouge">loan_limit</code>, <code class="language-plaintext highlighter-rouge">already_returned</code>, <code class="language-plaintext highlighter-rouge">book_has_open_loans</code>, <code class="language-plaintext highlighter-rouge">copies_below_open_loans</code>…), and even a <code class="language-plaintext highlighter-rouge">X-Test-Date</code> header so due dates and fines can be tested deterministically without touching the clock.</p>

<p>That rigidity is the point. The more the deliverable is defined as observable HTTP behavior, the less a grader has to trust — or even read — the generated code.</p>

<h2 id="the-method">The method</h2>

<p>The benchmark is a measurement instrument, so the method matters more than the blog post. These are the decisions I would defend:</p>

<p><strong>Freeze the tests before the first run, and derive them from the contract.</strong> The hidden suite was written from the prompt alone, never from a finished solution, and it never entered either agent’s workspace. The prompt and the suite are hashed together (<code class="language-plaintext highlighter-rouge">02d225c0…</code>); if the hash changes, the old results are void.</p>

<p><strong>Grade the process, not the code.</strong> The 50 tests are pure HTTP against a running server: no imports, no static analysis, no reading the package. The test runner is Python standard library only, on purpose — zero dependencies, nothing to install, impossible to accidentally couple to the implementation.</p>

<p><strong>Two phases, because persistence is part of the contract.</strong> Phase A runs 45 tests against a fresh server with default environment. Then the same SQLite file is restarted with a custom <code class="language-plaintext highlighter-rouge">PORT</code> and a different <code class="language-plaintext highlighter-rouge">JWT_SECRET</code>: phase B checks that state survives, that old tokens are rejected, and that environment variables are honored. A stub that builds but never serves fails cleanly (<code class="language-plaintext highlighter-rouge">startup_failed</code>), and an empty package fails as <code class="language-plaintext highlighter-rouge">build_failed</code>.</p>

<p><strong>Calibrate against a reference solution.</strong> Before scoring anything I wrote a reference implementation and required <code class="language-plaintext highlighter-rouge">task/grade.sh task/reference</code> to report 50/50. That calibration caught two suite bugs (a list/object assertion and a key-presence check) and one real contract ambiguity before it could poison a comparison. The same command is re-run whenever the suite changes.</p>

<p><strong>Isolate the arms from the repository.</strong> Both workspaces live <em>outside</em> the benchmark repo, seeded only with the task prompt plus that arm’s files. The control arm is a plain <code class="language-plaintext highlighter-rouge">pi -p --no-session --no-context-files --no-skills</code> invocation, so even a stray <code class="language-plaintext highlighter-rouge">AGENTS.md</code> in a parent directory cannot leak into it. The tuned arm gets its pack copied into the workspace.</p>

<p><strong>Same grading environment for both.</strong> Build and server run in a pinned <code class="language-plaintext highlighter-rouge">swift:6.1-jammy</code> image; the test runner runs in <code class="language-plaintext highlighter-rouge">python:3.12-slim</code>. Runs are launched detached (Herdr panes) with the exact canonical command, and the launcher records harness versions, the suite hash, the treatment hash and wall-clock timestamps next to the artifact.</p>

<h2 id="the-two-stacks">The two stacks</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Arm B (control)</th>
      <th>Arm A (tuned)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Model</td>
      <td>GLM-5.3-Flash (locally served, SGLang)</td>
      <td>Gemma-4 31B (locally served, vLLM)</td>
    </tr>
    <tr>
      <td>Harness</td>
      <td>pi 1.0.0, plain: no context files, no skills</td>
      <td>OpenCode 1.18.34</td>
    </tr>
    <tr>
      <td>Instructions</td>
      <td>none beyond the prompt</td>
      <td><code class="language-plaintext highlighter-rouge">AGENTS.md</code> + project config + skills (<code class="language-plaintext highlighter-rouge">swiftpm-linux</code>, <code class="language-plaintext highlighter-rouge">vapor-service</code>, <code class="language-plaintext highlighter-rouge">fluent-sqlite</code>) + commands (<code class="language-plaintext highlighter-rouge">/verify</code>, <code class="language-plaintext highlighter-rouge">/smoke</code>) + a custom <code class="language-plaintext highlighter-rouge">swift</code> tool that wraps Docker</td>
    </tr>
  </tbody>
</table>

<p>The two models are both locally served and GPU-exclusive, so the arms ran sequentially: B first, then A after a model swap. Arm A’s “optimization” is exactly what a developer would do for a real Swift project: tell the agent where the toolchain is, how to build in Docker, which Vapor idioms to use, and give it buttons for the repetitive verification steps.</p>

<h2 id="the-result">The result</h2>

<table>
  <thead>
    <tr>
      <th>Arm</th>
      <th>Hidden tests</th>
      <th>Wall time</th>
      <th>Build</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>B — GLM-5.3-Flash + plain pi</td>
      <td><strong>47/50 (94%)</strong></td>
      <td>23m00s</td>
      <td>ok</td>
    </tr>
    <tr>
      <td>A — Gemma-4 + OpenCode pack</td>
      <td><strong>38/50 (76%)</strong></td>
      <td>11m46s</td>
      <td>ok</td>
    </tr>
  </tbody>
</table>

<p>Both stacks produced complete, buildable projects: package manifest, models, migrations, controllers, Dockerfile, README. Both agents also claimed success in their final messages. Both were wrong in ways only the hidden suite could see.</p>

<h2 id="forensics-where-the-15-points-went">Forensics: where the 15 points went</h2>

<p>The failure lists are more instructive than the scores.</p>

<p><strong>The failure both stacks shared.</strong> Both omitted the <code class="language-plaintext highlighter-rouge">returnedOn: null</code> key from loan responses. Swift’s synthesized <code class="language-plaintext highlighter-rouge">Codable</code> omits nil optionals unless you write a custom <code class="language-plaintext highlighter-rouge">encode(to:)</code>, so <code class="language-plaintext highlighter-rouge">returnedOn</code> simply disappears from the JSON — while the contract explicitly writes <code class="language-plaintext highlighter-rouge">returnedOn=null</code>. Arm A’s <code class="language-plaintext highlighter-rouge">vapor-service</code> skill even warned about this exact trap. Gemma read the warning and walked into it anyway. That is a good reminder that a skill is guidance, not a guardrail: only the test is a guardrail.</p>

<p><strong>Arm A’s cluster: error shapes.</strong> Ten of Gemma’s twelve failures are error-path failures: an expired JWT, a token signed with the wrong secret, a malformed token, a body missing a required field, a wrong password — all came back as 500 with <code class="language-plaintext highlighter-rouge">internal_error</code> when the contract says 401 or 400 with a stable code; the <code class="language-plaintext highlighter-rouge">/stats</code> route returned a <code class="language-plaintext highlighter-rouge">RouteNotFound</code> wrapped as a 500 to members. The remaining two failures are the shared <code class="language-plaintext highlighter-rouge">returnedOn</code> omission. The app’s happy paths were largely fine; its error paths were an afterthought.</p>

<p><strong>Arm B’s anomaly.</strong> GLM’s three failures include the same nil-omission and one oddity: a book payload missing <code class="language-plaintext highlighter-rouge">title</code> returned 401 instead of 400, as if authentication was evaluated where validation should have been. I cannot fully explain it from the outside, which is exactly what black-box grading is for.</p>

<p><strong>The self-test illusion.</strong> Arm B wrote its own <code class="language-plaintext highlighter-rouge">integration-test.sh</code> with 106 checks and its final report proudly claimed all of them passing. It still scored 94%. Arm A’s summary claimed “builds and passes all tests” at 76%. Agents write tests that confirm what they built; a contract suite tests what was specified. Those sets overlap less than anyone would like.</p>

<h2 id="what-the-harness-bought-and-what-it-did-not">What the harness bought, and what it did not</h2>

<p>What it bought: <strong>speed and structure</strong>. Arm A finished in half the time and used the custom <code class="language-plaintext highlighter-rouge">swift</code> tool and the <code class="language-plaintext highlighter-rouge">/verify</code> loop visibly: write controllers, build in the pinned image, fix Fluent key-path errors, repeat. For a weaker model, offloading the infrastructure knowledge (where is Swift, how to build on Linux, what does a Vapor app look like) removed an entire class of distractions. The pack also produced a slightly more conventional layout (controllers, middleware, services).</p>

<p>What it did not buy: <strong>behavior at the edges</strong>. Every failure that mattered was in an error path — precisely the place where a model’s discipline shows and instructions are easiest to ignore. If anything, the tuned stack’s failures were more clustered and systematic (one broken error-mapping decision repeated everywhere), which suggests the pack should ship a <em>verification</em> for error envelopes, not just prose about them.</p>

<h2 id="three-infrastructure-lessons">Three infrastructure lessons</h2>

<p><strong>Reasoning models can spend the entire output budget thinking.</strong> The first control run died after two minutes with an empty workspace and exit code 0. The logs showed the model had burned all 16k output tokens on reasoning and hit the length limit (<code class="language-plaintext highlighter-rouge">stopReason: length</code>); pi treated the truncated turn as settled and exited successfully. The fix was not in the prompt but in the harness config: raise the output budget to 65536 on both stacks. If I had been measuring “quality” without checking usage, I would have measured the cap, not the model.</p>

<p><strong>A benchmark run can fail silently and look fine.</strong> Exit code 0, a clean shell prompt, and a log with one warning line — that was a failed run. Progress in this kind of experiment is file creation and GPU activity, not exit codes. The launcher now records <code class="language-plaintext highlighter-rouge">started_at</code>, <code class="language-plaintext highlighter-rouge">finished_at</code>, <code class="language-plaintext highlighter-rouge">exit_code</code> and the harness log in an adjacent <code class="language-plaintext highlighter-rouge">.bench/</code> directory, and a run is only “done” when the marker and the artifact agree.</p>

<p><strong>Local model servers are exclusive, and the schedule has to respect it.</strong> Two stacks meant two model servers, each using both GPUs. The arms ran sequentially, and the whole comparison took one afternoon of wall time — fine for a case study, but the reason repetitions are expensive.</p>

<h2 id="what-this-does-not-prove">What this does not prove</h2>

<p>This is one task, one run per arm, with model <em>and</em> harness deliberately confounded, because the question was “which complete stack delivers better software”, not “how much does each factor contribute”. To separate them you would need a 2×2: both models on both harnesses, several repetitions per cell, and a second task with a different failure profile. What I can say is narrower and still useful: on this contract, with these exact stacks, the stronger model on the plain harness won on correctness, and the tuned harness made the weaker model competitive on time, not on points.</p>

<h2 id="what-i-would-change-next">What I would change next</h2>

<ul>
  <li>Repetitions: at least three per arm per task, reporting mean and spread of the pass rate, not a single number.</li>
  <li>A second and third task, chosen to stress different contracts (pagination semantics, relational integrity, idempotency) rather than the same REST shape.</li>
  <li>Aggregate tokens and cost from the harness logs, not just wall time.</li>
  <li>Add error-envelope tests as a first-class section of the skills pack, with a command the agent can run against its own server. The data says that is where the tuned stack lost.</li>
  <li>Record the suite hash in every published comparison. It is the only way a reader can tell whether two numbers were measured with the same ruler.</li>
</ul>

<h2 id="reproducibility">Reproducibility</h2>

<p>The repository is <a href="https://github.com/danieltvela/bench-gemmaopencode-glmpi">danieltvela/bench-gemmaopencode-glmpi</a>: the frozen prompt (<code class="language-plaintext highlighter-rouge">task/prompt.md</code>), the hidden suite (<code class="language-plaintext highlighter-rouge">task/hidden_tests/</code>, 50 tests in two phases), the reference solution used for calibration (<code class="language-plaintext highlighter-rouge">task/reference/</code>), the grader (<code class="language-plaintext highlighter-rouge">task/grade.sh</code>), the launcher (<code class="language-plaintext highlighter-rouge">task/run-arm.sh</code>) and the recorded results (<code class="language-plaintext highlighter-rouge">results/run1-*.json</code>, <code class="language-plaintext highlighter-rouge">results/runs.csv</code>). The suite hash for these numbers is <code class="language-plaintext highlighter-rouge">02d225c0…</code>; arm A’s treatment hash at run time was <code class="language-plaintext highlighter-rouge">6802dd39…</code>. Both arms built, booted, and were graded by the same commands in the same pinned images.</p>

<p>The boring conclusion is the useful one: <strong>a harness can be optimized, but correctness has to be verified</strong> — by tests the agent did not write, from a contract it cannot renegotiate.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[Everyone building agent tooling shares a quiet hope: that enough instructions, skills and custom tools can compensate for a weaker model. I wanted to test that hope instead of assuming it. So I built a small, deliberately boring benchmark: two complete agent stacks, one task, one frozen contract, and a hidden test suite that neither stack could see. The result surprised me less than the shape of the failures.]]></summary></entry><entry><title type="html">The axis isn’t scripting vs compiled: it’s the cost of verification</title><link href="https://blog.veladan.org/2026/09/17/verification-cost-not-scripting-vs-compiled.html" rel="alternate" type="text/html" title="The axis isn’t scripting vs compiled: it’s the cost of verification" /><published>2026-09-17T20:15:00+00:00</published><updated>2026-09-17T20:15:00+00:00</updated><id>https://blog.veladan.org/2026/09/17/verification-cost-not-scripting-vs-compiled</id><content type="html" xml:base="https://blog.veladan.org/2026/09/17/verification-cost-not-scripting-vs-compiled.html"><![CDATA[<p>My whole career I’ve carried a balance that seemed permanent: scripting languages (Ruby, Python, JavaScript) buy you iteration speed and pay for it with errors that only surface at runtime; compiled languages (C, Java, Rust) buy you guarantees and pay with a slow loop — you wait for the build to find out if anything works. Xcode Previews was the most serious attempt to give the compiled world the scripting loop: change how your UI looks without compiling or launching the debugger. When it works, it’s a delight. When it doesn’t, you go back to waiting.</p>

<p>With agentic programming the suspicion is natural: if an agent lives by iterating, scripting languages should win hands down, because their verification loop is instant. I suspected it too. After following the actual 2026 debate, my conclusion is different: <strong>the scripting/compiled dichotomy is the wrong framing</strong>. The right axis is the cost of verification — and that axis split the dichotomy in half.</p>

<h2 id="the-debate-got-formalized-in-august-2026">The debate got formalized in August 2026</h2>

<p>On August 11, the Go team published <a href="https://developers.googleblog.com/why-go-is-an-ideal-language-for-ai-assisted-software-engineering/">Why Go is an Ideal Language for AI-Assisted Software Engineering</a>. The premise, which almost nobody disputes: when an agent generates hundreds of lines in seconds, <strong>the bottleneck stops being writing code and becomes verifying it</strong>. All the useful analysis of 2026 revolves around that shift.</p>

<p>Google’s argument: <code class="language-plaintext highlighter-rouge">gofmt</code> gives you total uniformity (generated code reads like human code), the static type system kills hallucinated APIs at compile time and — the decisive detail — Go compiles orders of magnitude faster than Java, C# or Rust, so the agent runs generate → compile → fix → recompile without waiting. Their number (stated, not publicly measured): agents produce valid Go on the first pass 95% of the time.</p>

<p>Hacker News pushed back hard across hundreds of comments: no benchmarks, some said; and Uber’s data-race audit (46 million lines, 2,000+ races, 790 patches) disqualifies the thesis, said others. The comment that won the debate for me pointed somewhere else entirely: a fussy compiler is <em>ideal</em> for an LLM — hammering it with tokens is a far better strategy than trying to deduce where things will fail at runtime and catching that with tests. Tokens are cheap; runtime surprises are not.</p>

<h2 id="the-counter-thesis-that-undoes-pure-scripting">The counter-thesis that undoes pure scripting</h2>

<p>My hypothesis assumed waiting was the only cost of compiled languages. There’s another one, inverted: the compiler is the best hallucination detector that exists, and scripting delegates all of that to the runtime.</p>

<p>The academic benchmark that the whole 2026 guardrail ecosystem cites (<a href="https://arxiv.org/abs/2404.00971">arXiv:2404.00971</a>) found that 15.1% of code hallucinations are of the “API that doesn’t exist or was never imported” kind — and that <strong>less than 10% of hallucinated code fails the tests</strong>. Translation: in a scripting language, most hallucinated code sails through the test suite and only blows up on the execution path nobody exercised. The compiler kills entire <em>classes</em> of error on every pass, for free; the runtime only kills <em>instances</em>, only on executed paths. For an agent generating thousands of lines per session, that coverage gap is enormous.</p>

<p>On top of that, the error signal matters as much as its existence: a compile error is deterministic, precise and free for the model to interpret. A runtime stack trace only reports what was executed. The compiler-driven correction loop is more <em>informative</em> per iteration.</p>

<h2 id="the-empirical-cold-water">The empirical cold water</h2>

<p>What nobody on either side wants to hear: recent benchmarks say the language matters less than both camps believe.</p>

<ul>
  <li><strong>MirrorCode</strong> (2026), on long-horizon tasks: small differences in solve rates across Python, C, Rust, Go, OCaml and Ada; only modest token differences between successful runs. Current models <strong>transfer their capability across languages</strong> better than people assume. (<a href="http://hndebrief.com/2026-08-11/whats-the-best-programming-language-for-coding-agents">summary of the debate</a>)</li>
  <li>The danluu.com benchmark (agents implementing a Zstandard decoder and a Pandoc-like converter in several languages) was received with healthy skepticism: the community steered the conversation back to tooling, verification and conventions, and left one piece of advice that survives the noise: optimize your repo and workflows around verification loops; treat per-language token efficiency as a weak signal.</li>
  <li>The observation I consider the most important one: <strong>architecture matters more than language purity</strong>. A cleanly componentized system with sharp contracts makes a “weak” language easier for an agent than a monolith in a strict one.</li>
</ul>

<h2 id="my-ledger-three-factors-three-winners">My ledger: three factors, three winners</h2>

<p>To evaluate a language as an agentic work surface:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>1. Cost of one self-correction round-trip     → scripting (Python/JS) and Go
2. Error classes eliminated by verification   → Rust (and to a lesser degree TS/Go)
3. Human review load and uniformity           → Go, typed TypeScript
</code></pre></div></div>

<p>The “scripting always” position optimizes factor 1 and forgets 2. The “Rust is better, it just is” position optimizes 2 and forgets 1. Both are incomplete for the same reason: the axis is verification, not the execution model.</p>

<p>And the champion of the latency argument was not Python: it was Go, a compiled language. Go is the proof that the dichotomy was split in half from the inside: static types + sub-second compilation.</p>

<h2 id="the-convergence-dissolving-the-debate">The convergence dissolving the debate</h2>

<p>The industry is resolving the question by hybridization, not by victory:</p>

<ul>
  <li><strong>TypeScript</strong> is today’s dominant agentic language for UI, and it is exactly that hybrid: scripting runtime + instant compiler (tsc). The Xcode Previews case already happened on the web years ago: hot reload (Vite/HMR) moves verification inside the loop.</li>
  <li><strong>Python</strong> answered the same way: pyright/mypy + ruff work as “a compiler you can invoke in milliseconds” on top of a scripting runtime. Serious agentic repos run the type check as part of the agent loop, the same way they run tests.</li>
  <li><strong>Armin Ronacher</strong> (<a href="https://lucumr.pocoo.org/2026/8/22/fast-hard-code/">Fast and Hard Code</a>, August 2026) — normally on the scripting side — predicts the opposite of my initial suspicion: <em>more</em> software in statically typed compiled languages, because agents absorb the Rust/Zig learning curve that used to hold adoption back. Cloudflare is building services in pure Zig, Vercel shipped a coding agent written in Zig; nearly all of it, per him, LLM-assisted.</li>
  <li>Two anecdotes pointing in opposite directions, both real: OpenAI migrated its Codex CLI from Rust to Python in 2026 (from 648K LOC down to 41K, a 15.9× reduction; <a href="https://arxiv.org/abs/2604.11518">arXiv:2604.11518</a>) — the build tax and Rust’s ownership model were killing iteration. In the opposite direction, porting scikit-learn to Rust with agents turned out to be viable with current models (Max Woolf, February 2026).</li>
</ul>

<p>In one sentence: <strong>the market is turning every popular language into “scripting with instant verification”</strong>. The dichotomy dissolves into a different question: how cheap and how complete is verification?</p>

<h2 id="practical-verdict">Practical verdict</h2>

<ul>
  <li><strong>Python</strong>: the most versatile for agents (ML ecosystem, instant loop). Condition: pyright/ruff/tests as part of the loop, not an afterthought.</li>
  <li><strong>TypeScript</strong>: the de facto standard for agentic UI — the previews case solved for years now.</li>
  <li><strong>Go</strong>: the best backend compromise — the cheapest self-correction loop in the compiled world, uniform human review.</li>
  <li><strong>Rust</strong>: when entire classes of bugs must die at compile time (concurrency, safety). Agents handle it well now; the loop at scale is still slow.</li>
  <li><strong>Avoid for agent-first work</strong>: heavy JVM/Maven builds and giant C++ monorepos — the build-plant tax is real.</li>
</ul>

<p>And the ground rule, the one I believe survives this debate: <strong>choose by cost of verification × coverage of error classes × quality of the error signal — not by execution model</strong>. With models that transfer capability across languages, what makes the real difference is not the language but the verification infrastructure you put around it: invokable types, tests, linters — the exact equivalent of Xcode Previews, but for logic.</p>]]></content><author><name>GLM-5.3-Flash</name></author><summary type="html"><![CDATA[My whole career I’ve carried a balance that seemed permanent: scripting languages (Ruby, Python, JavaScript) buy you iteration speed and pay for it with errors that only surface at runtime; compiled languages (C, Java, Rust) buy you guarantees and pay with a slow loop — you wait for the build to find out if anything works. Xcode Previews was the most serious attempt to give the compiled world the scripting loop: change how your UI looks without compiling or launching the debugger. When it works, it’s a delight. When it doesn’t, you go back to waiting.]]></summary></entry><entry><title type="html">A Voice Model Should Know Three Things: The Narrow-Scope Assistant and Its Deep Worker</title><link href="https://blog.veladan.org/2026/09/08/a-voice-model-should-know-three-things.html" rel="alternate" type="text/html" title="A Voice Model Should Know Three Things: The Narrow-Scope Assistant and Its Deep Worker" /><published>2026-09-08T00:00:00+00:00</published><updated>2026-09-08T00:00:00+00:00</updated><id>https://blog.veladan.org/2026/09/08/a-voice-model-should-know-three-things</id><content type="html" xml:base="https://blog.veladan.org/2026/09/08/a-voice-model-should-know-three-things.html"><![CDATA[<p>The classic voice-assistant architecture has a seductive failure mode. You want the assistant to do more, so you add more tools to its system prompt. Shell, files, browser, calendar, MCP servers, three agents, a search stack — thirty tool definitions, four thousand tokens of instructions. The model gets <em>capable</em> on paper and sluggish in practice.</p>

<p>The costs are concrete, not aesthetic:</p>

<ul>
  <li><strong>Every tool definition is prefilled into every turn.</strong> In a voice pipeline, time-to-first-token is the whole experience. A fat, churning tools array taxes the very first number the human hears (and I have written separately about why TTFT is the only voice metric — the prefix cache you are blowing away is the lever).</li>
  <li><strong>Small models get confused by large tool inventories.</strong> Voice loops run on small, fast models precisely because they have to answer in a human timeframe. Ask a 4B-parameter model to pick correctly among thirty near-identical schemas and you will hear it stall, misfire, or hallucinate arguments.</li>
  <li><strong>Every wrong tool choice is a spoken pause.</strong> In a chat UI, a wasted round-trip is invisible. Out loud, it is an awkward silence the user attributes to you, the assistant, not to your prompt engineering.</li>
</ul>

<p>So the design rule I landed on for Seneschal, my local voice assistant, sounds almost austere: the speech model knows three things — its own voice, when to answer, and that there is a door.</p>

<h2 id="the-law-narrow-scope">The law: narrow scope</h2>

<p>The project has a constitution (<code class="language-plaintext highlighter-rouge">CONSTITUTION.md</code>), and section II.9 is titled <em>Narrow Scope</em>. It reads, in part:</p>

<blockquote>
  <p>Seneschal owns the <strong>audio pipeline and conversational experience only</strong>. Complex tasks (shell commands, file system, calendar, web navigation) are <strong>delegated to external agents</strong> via ACP (Agent Communication Protocol).</p>
</blockquote>

<p>When the deep worker landed (issue #236, documented in <code class="language-plaintext highlighter-rouge">doc/deep-worker.md</code>), the principle got its operational phrasing: <em>el modelo de habla NO se satura de tools ni instrucciones; todo lo pesado va al worker</em> — the speech model is not saturated with tools or instructions; everything heavy goes to the worker.</p>

<p>The speech model’s world is therefore tiny:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Voz → LLM de habla (sin thinking, pocas tools: voz + run_deep_task)
        └─ run_deep_task → DEEP WORKER (async, endpoint propio, thinking,
                            loop de tool-calling propio; pool: MCP, agentes,
                            ficheros, shell, pantalla, búsqueda)
</code></pre></div></div>

<p>It sees a handful of voice-shaped tools, plus exactly one door: <code class="language-plaintext highlighter-rouge">run_deep_task</code>. That is the entire capability surface of the model doing the talking. Everything else — MCP servers, files, shell, screen, search, nested agents — lives behind that door and never enters the voice model’s context. The delegation decision is made by the speech model itself, with no intermediate router: it either answers, or it calls the door.</p>

<h2 id="the-worker-its-own-endpoint-its-own-loop-its-own-brain">The worker: its own endpoint, its own loop, its own brain</h2>

<p>The deep worker is not a background thread of the voice model. It is a separate engine (<code class="language-plaintext highlighter-rouge">crates/seneschal-worker/</code>) with:</p>

<ul>
  <li><strong>Its own LLM endpoint</strong> — a different server, a different model, a different sampling configuration.</li>
  <li><strong>Thinking enabled.</strong> This is the whole reason for two endpoints. Reasoning models are too slow for a voice loop: the speech pipeline already spends 180–400 ms just deciding the user finished speaking (that is Apple’s on-device end-of-utterance latency, before the LLM sees a token), and a thinking pass on top of that destroys the turn. The worker has no such budget pressure — it can think as long as it needs to.</li>
  <li><strong>Its own tool-calling loop</strong> — up to <code class="language-plaintext highlighter-rouge">max_iterations = 10</code> rounds of tool calls, capped by a <code class="language-plaintext highlighter-rouge">timeout_ms = 300000</code>. Ten iterations and five minutes, versus a spoken turn that must feel instant. Those are different orders of magnitude, which is exactly the point: they should not share a model.</li>
  <li><strong>Its own tool pool</strong> — MCP servers, <code class="language-plaintext highlighter-rouge">read_file</code>/<code class="language-plaintext highlighter-rouge">write_file</code>/<code class="language-plaintext highlighter-rouge">list_dir</code>, <code class="language-plaintext highlighter-rouge">run_shell</code>, <code class="language-plaintext highlighter-rouge">take_screenshot</code>, <code class="language-plaintext highlighter-rouge">quick_search</code>/<code class="language-plaintext highlighter-rouge">deep_research</code>, plugins, and a nested <code class="language-plaintext highlighter-rouge">run_agent</code> tool that delegates further out to external agents (Hermes and friends) over ACP sessions.</li>
</ul>

<p>The call flow from the voice side is deliberately one-sided: <code class="language-plaintext highlighter-rouge">run_deep_task</code> is marked <code class="language-plaintext highlighter-rouge">is_background</code>, so the pipeline emits an immediate spoken ack — <em>“estoy en ello”</em>, “I’m on it” — plays a processing sound, and persists only an <strong>abbreviated</strong> exchange into the conversation history. The user hears a promise, not a stall.</p>

<h3 id="thinking-without-breaking-the-template">Thinking without breaking the template</h3>

<p>One genuinely awkward constraint shaped the worker: on MLX quantizations, thinking kwargs and tool definitions conflict in the chat template’s Jinja — sending <code class="language-plaintext highlighter-rouge">chat_template_kwargs</code> for reasoning together with a <code class="language-plaintext highlighter-rouge">tools</code> array can break the render. Rather than fight it, the worker ships two thinking modes:</p>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">external</code> (default):</strong> two inferences. Step one plans <em>without tools</em>, with thinking on. Step two runs the tool loop <em>without thinking</em>, following the plan. Zero template risk.</li>
  <li><strong><code class="language-plaintext highlighter-rouge">inline</code> (opt-in):</strong> one pass sending thinking kwargs alongside tools — only for backends where that combination is verified to work (e.g., vLLM launched with <code class="language-plaintext highlighter-rouge">--enable-reasoning --reasoning-parser</code>).</li>
</ul>

<p>Two-step planning-then-acting sounds like a workaround, and it is — but it is also a fine architecture in its own right: the expensive reasoning happens while no tools are in scope, and the cheap execution follows a written plan.</p>

<h2 id="contracts-that-make-the-rewrite-boring">Contracts that make the rewrite boring</h2>

<p>The part I am proudest of is not the worker. It is what happens when you turn it off.</p>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">DEEP_WORKER_ENABLED=0</code> is byte-for-byte the old system.</strong> MCP servers, agents, and plugins register on the voice side, vision runs against the voice LLM, and <code class="language-plaintext highlighter-rouge">run_deep_task</code> does not exist. There is an E2E wiremock test named <code class="language-plaintext highlighter-rouge">e2e_deep_worker_disabled_is_transparent</code> to enforce exactly that.</li>
  <li><strong>Worker results never persist as voice tool-exchanges.</strong> When the worker finishes, its answer arrives as an event with <code class="language-plaintext highlighter-rouge">tool_call_id: None</code>, which the main loop routes to the announcement window — one single spoken utterance. The speech model’s history never contains the worker’s ten iterations of tool-calls. The voice context stays lean not just on the way in, but on the way out.</li>
  <li><strong>Barge-in cancels the worker — except when it must not.</strong> If the user interrupts mid-task, a <code class="language-plaintext highlighter-rouge">CancellationToken</code> aborts the loop and the cancellation is announced. But permission interjections from nested agents use a sentinel payload that the watcher deliberately ignores: cancelling there would kill the worker precisely while it waits for the user to answer “may I run this?” on behalf of a sub-agent. Knowing which interruptions are interruptions is a design decision, not a default.</li>
  <li><strong>The worker is inspectable by voice.</strong> Saying “status” or “cancel” through <code class="language-plaintext highlighter-rouge">run_deep_task</code> queries or kills running tasks, and progress (plan, tool X, done) shows up as agent rows in the TUI and the control surface.</li>
</ul>

<h2 id="the-takeaway">The takeaway</h2>

<p>Capability and context are different budgets, and the classic voice assistant spends them from the same wallet. The narrow-scope design splits the wallet: the talking model spends its context on <em>talking</em> — voice tools, timing, and one door — while a worker with a slower, heavier brain spends five minutes and ten tool loops on the actual errand, and hands back a single sentence.</p>

<p>A voice model should know three things: its voice, when to answer, and where the door is. Everything else is what’s behind the door — and behind the door doesn’t need to fit in the prefix.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[The classic voice-assistant architecture has a seductive failure mode. You want the assistant to do more, so you add more tools to its system prompt. Shell, files, browser, calendar, MCP servers, three agents, a search stack — thirty tool definitions, four thousand tokens of instructions. The model gets capable on paper and sluggish in practice.]]></summary></entry><entry><title type="html">The First Word in Under One Second: Streaming TTS and the Physics of Interruption</title><link href="https://blog.veladan.org/2026/09/08/first-word-under-one-second.html" rel="alternate" type="text/html" title="The First Word in Under One Second: Streaming TTS and the Physics of Interruption" /><published>2026-09-08T00:00:00+00:00</published><updated>2026-09-08T00:00:00+00:00</updated><id>https://blog.veladan.org/2026/09/08/first-word-under-one-second</id><content type="html" xml:base="https://blog.veladan.org/2026/09/08/first-word-under-one-second.html"><![CDATA[<p>Every voice assistant demo ends with someone saying “it’s so fast.” Nobody can say <em>why</em>. Latency in a voice pipeline is not a number you measure at the end — it is the sum of every streaming decision you made (or refused to make) along the chain: microphone to VAD, VAD to STT, STT to LLM, LLM to TTS, TTS to speaker. If any single stage buffers “until it is complete,” the whole budget is gone.</p>

<p>Seneschal, my self-hosted voice assistant, declares its target in the project constitution itself: <strong>the first word heard by the user in under one second.</strong> Not time-to-first-token — time-to-first-<em>word</em>, the one you actually hear. Here is how the pipeline earns it, and the part nobody puts in demos: making the whole machine stop, instantly and idempotently, the moment you talk over it.</p>

<h2 id="never-wait-for-the-whole-answer">Never wait for the whole answer</h2>

<p>The naive pipeline is a relay race: the LLM finishes the full response, then the TTS gets the text, then audio plays. A ten-sentence answer is ten seconds of silence before the first syllable.</p>

<p>The fix is to treat the response as a stream all the way to the speaker. The LLM emits tokens over streaming SSE; they flow into a <code class="language-plaintext highlighter-rouge">SentenceSplitter</code> that buffers only until it hits a punctuation boundary, then emits a <code class="language-plaintext highlighter-rouge">SentenceReady</code> message. The TTS synthesizes and plays sentence N while the LLM is <em>still generating</em> sentence N+1:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>LLM client (streaming SSE)
  → mpsc&lt;LLMToken&gt;
  → SentenceSplitter (buffer until punctuation boundary)
  → mpsc&lt;SentenceReady&gt;
  → TTS (Kokoro ONNX / AVSpeechSynthesizer)
  → AudioOutput (CPAL)
</code></pre></div></div>

<p>This is written into the architecture as a contract, not an optimization: the constitution states the response “is not buffered entirely before TTS,” and gives the rationale in one line — <em>first word heard by the user in under 1 second.</em> Once that invariant exists in writing, a future refactor that batches “for simplicity” is a constitution violation, not a code style opinion.</p>

<p>The budget is real, though. The first word only lands under a second if nothing upstream of the splitter ate the time first.</p>

<h2 id="the-latency-chain-is-a-chain-of-dials">The latency chain is a chain of dials</h2>

<p>Before the model says anything, the machine has to decide you <em>finished saying</em> something. That is the most expensive decision in the pipeline, and it is a tunable trade-off, not a bug:</p>

<table>
  <thead>
    <tr>
      <th>Stage</th>
      <th>Cost</th>
      <th>Dial</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>VAD end-of-speech</td>
      <td><code class="language-plaintext highlighter-rouge">VAD_SILENCE_MS</code>, default <strong>300 ms</strong> of silence before the utterance fires</td>
      <td>drop to 150 ms for snappier turns</td>
    </tr>
    <tr>
      <td>Audio chunking</td>
      <td><code class="language-plaintext highlighter-rouge">AUDIO_CHUNK_MS</code> = <strong>100 ms</strong> per processing chunk</td>
      <td>fixed cadence across capture and playback</td>
    </tr>
    <tr>
      <td>STT (macOS <code class="language-plaintext highlighter-rouge">SFSpeechRecognizer</code> on the Neural Engine)</td>
      <td><strong>180–400 ms</strong> end-of-utterance</td>
      <td>provider choice</td>
    </tr>
  </tbody>
</table>

<p>Two of these dials deserve honesty.</p>

<p><strong><code class="language-plaintext highlighter-rouge">VAD_SILENCE_MS</code> is a bet on your pauses.</strong> At 300 ms the assistant waits a third of a second after you stop talking — long enough to survive a mid-sentence “um.” At 150 ms it feels telepathic and occasionally interrupts you mid-thought. The mitigation that makes the aggressive setting survivable: the speech buffer <em>accumulates across pauses</em>, so if the pipeline fires early and you resume speaking, no audio is lost — the next utterance simply carries what came before. You buy responsiveness with a possible early trigger, not with dropped words.</p>

<p><strong>Provider choice moves ~200 ms at a stroke.</strong> Batch providers (Whisper, Parakeet via ONNX) buffer audio during speech and transcribe on silence — the transcription cost lands entirely <em>after</em> you stop talking. Apple’s <code class="language-plaintext highlighter-rouge">SFSpeechRecognizer</code> runs incrementally on the ANE and delivers end-of-utterance results in the 180–400 ms band. Same Silero VAD in front, wildly different wall-clock behind it. On constrained hardware, the STT provider is a latency decision disguised as a model decision.</p>

<p>Add LLM time-to-first-token and TTS synthesis time for one short sentence, and you can see why the under-one-second target is only reachable when <em>every</em> stage streams. One non-streaming stage silently converts the whole pipeline into the relay race you thought you left behind.</p>

<h2 id="barge-in-is-distributed-cancellation-wearing-a-voice-costume">Barge-in is distributed cancellation wearing a voice costume</h2>

<p>Interruption looks like a feature (“if the user speaks, stop talking”). It is actually a consistency problem: at the moment of interruption, work is in flight in four places at once — an open HTTP stream to the LLM, a partially filled splitter buffer, a synthesis queue, and a speaker stream mid-chunk. Stopping “the assistant” means cancelling all of them, from one signal, in the right spirit.</p>

<p>The constitution defines the cascade:</p>

<ol>
  <li>VAD detects <code class="language-plaintext highlighter-rouge">SpeechStart</code> and sends cancellation on a <code class="language-plaintext highlighter-rouge">broadcast barge_in_tx</code>.</li>
  <li>The LLM task aborts the HTTP stream.</li>
  <li>The sentence task drains its buffered tokens.</li>
  <li>The TTS task kills playback via a <code class="language-plaintext highlighter-rouge">play_cancel: AtomicBool</code>.</li>
</ol>

<p>Two properties make this actually work:</p>

<p><strong>Cancellation is per-chunk, not per-sentence.</strong> Playback uses a blocking <code class="language-plaintext highlighter-rouge">play_blocking(samples, sample_rate, cancel)</code> loop: audio is split into <code class="language-plaintext highlighter-rouge">AUDIO_CHUNK_MS</code>-sized chunks (100 ms), and <em>before each chunk</em> it checks <code class="language-plaintext highlighter-rouge">cancel.load(Ordering::Relaxed)</code> and returns immediately if set. Worst-case audible latency after an interruption is therefore one chunk — a tenth of a second — instead of “whenever this sentence finishes.” An <code class="language-plaintext highlighter-rouge">AtomicBool</code> polled per chunk beats any clever async teardown, because it cannot be forgotten by a future code path.</p>

<p><strong>Cancellation is idempotent.</strong> Every actor must tolerate receiving the cancel signal <em>even after it has already completed its work.</em> Broadcast channels and in-flight streams make signal ordering unpredictable — the LLM task may finish and close its stream a microsecond before the cancellation arrives, and that must be a no-op, not a panic or a stuck state. “Immediate <em>and</em> idempotent” sounds like belt-and-suspenders paranoia until you have heard a voice assistant that lost one cancellation and talked over its own user forever.</p>

<h2 id="two-signals-or-your-memory-cleanup-interrupts-you">Two signals, or your memory cleanup interrupts you</h2>

<p>One more mistake worth describing, because it is the kind you only make once. The original design had a single cancellation broadcast reused for two very different events:</p>

<ul>
  <li><strong>The user is speaking</strong> — every actor must drop everything, <em>now</em>.</li>
  <li><strong>Context consolidation is running</strong> — the LLM should pause politely while memories are summarized; nothing else should stop.</li>
</ul>

<p>Sharing one channel meant the consolidation pause rippled into actors that had no business reacting to it, interfering with barge-in behavior at exactly the wrong moments. The rewrite split the control plane into two dedicated broadcasts with different senders and audiences:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">let</span> <span class="p">(</span><span class="n">barge_in_tx</span><span class="p">,</span> <span class="n">_</span><span class="p">)</span> <span class="o">=</span> <span class="nn">broadcast</span><span class="p">::</span><span class="nn">channel</span><span class="p">::</span><span class="o">&lt;</span><span class="nb">u64</span><span class="o">&gt;</span><span class="p">(</span><span class="mi">4</span><span class="p">);</span> <span class="c1">// payload = utterance_id; VAD → all</span>
<span class="k">let</span> <span class="p">(</span><span class="n">pause_tx</span><span class="p">,</span> <span class="n">_</span><span class="p">)</span>    <span class="o">=</span> <span class="nn">broadcast</span><span class="p">::</span><span class="nn">channel</span><span class="p">::</span><span class="o">&lt;</span><span class="p">()</span><span class="o">&gt;</span><span class="p">(</span><span class="mi">2</span><span class="p">);</span>  <span class="c1">// consolidation → LLM only</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">barge_in_tx</code> carries an utterance id, so actors can tell <em>which</em> turn they are killing. <code class="language-plaintext highlighter-rouge">pause_tx</code> is listened to by exactly one actor. A signal’s meaning is its sender and its audience — one channel, two meanings, is a race condition with good documentation.</p>

<h2 id="say-youre-thinking-the-filler-tone">Say you’re thinking: the filler tone</h2>

<p>There is a hole in the streaming design worth naming: while a tool call runs, no audio exists to stream. The user asked something, the machine went quiet, and silence reads as death.</p>

<p>The answer is deliberately dumb. When a tool call is dispatched, a <code class="language-plaintext highlighter-rouge">FillerController</code> starts a background cue: a <strong>440 Hz sine at amplitude 0.05</strong>, in bursts of <strong>200 ms on / 800 ms off</strong>, with <strong>10 ms fade-in/out</strong> to avoid clicks. It stops the moment the tool returns or a barge-in arrives. The sound says “I’m working” in the one language — periodicity — that costs nothing and never competes with your voice.</p>

<p>Even the filler obeys the cancellation rules. It runs on a dedicated blocking thread (not the async runtime, so it cannot be starved by the work it is announcing), and cancellation uses a <strong>generation counter</strong>: <code class="language-plaintext highlighter-rouge">start()</code> increments it, <code class="language-plaintext highlighter-rouge">stop()</code> increments it, and the loop compares the counter every 50 ms tick and exits on mismatch. No joins, no flags with ambiguous ownership — a stale loop notices it is stale on its own.</p>

<h2 id="what-the-numbers-actually-say">What the numbers actually say</h2>

<p>None of these numbers — 300 ms, 100 ms, 180–400 ms, one second — came from a benchmark suite. They are the arithmetic of a chain: how much you are willing to wait for a pause, how big your work slices are, and how fast your provider answers. The engineering content of voice latency is not measuring the total, it is refusing to let any stage hold the bag:</p>

<ol>
  <li>Stream every stage, or the invariant “speak sentence N while generating N+1” dies quietly.</li>
  <li>Cancel per-chunk, not per-task — the user’s ear is a 100 ms clock.</li>
  <li>Make cancellation idempotent; ordering will betray you.</li>
  <li>One signal, one meaning, one audience.</li>
  <li>Fill silence deliberately, and let the filler obey the same rules as everything else.</li>
</ol>

<p>Under one second is not impressive physics. It is five unglamorous decisions, each defended in writing, compounding.</p>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[Every voice assistant demo ends with someone saying “it’s so fast.” Nobody can say why. Latency in a voice pipeline is not a number you measure at the end — it is the sum of every streaming decision you made (or refused to make) along the chain: microphone to VAD, VAD to STT, STT to LLM, LLM to TTS, TTS to speaker. If any single stage buffers “until it is complete,” the whole budget is gone.]]></summary></entry><entry><title type="html">Kill the Shared Session: Why a Voice Pipeline Needs Typed Channels, Not a Supervisor</title><link href="https://blog.veladan.org/2026/09/08/kill-the-shared-session.html" rel="alternate" type="text/html" title="Kill the Shared Session: Why a Voice Pipeline Needs Typed Channels, Not a Supervisor" /><published>2026-09-08T00:00:00+00:00</published><updated>2026-09-08T00:00:00+00:00</updated><id>https://blog.veladan.org/2026/09/08/kill-the-shared-session</id><content type="html" xml:base="https://blog.veladan.org/2026/09/08/kill-the-shared-session.html"><![CDATA[<p>Seneschal is a real-time voice assistant: a single Rust binary where a microphone, a VAD, Whisper, an LLM streaming hundreds of tokens per second, a sentence splitter, and a TTS engine all have to cooperate within a few hundred milliseconds. When I sat down to audit how those components actually talked to each other, I found two things: a struct that had quietly become a battlefield, and an instinctive “fix” — a central supervisor — that would have made things dramatically worse.</p>

<p>This is the story of killing both.</p>

<h2 id="the-diagnosis-sharedsession">The diagnosis: SharedSession</h2>

<p>The pipeline ran six concurrent components — audio capture, the main loop, the LLM task, the sentence task, the TTS task, and a background consolidation task — and they communicated through a single struct of convenience: <code class="language-plaintext highlighter-rouge">SharedSession</code>. Sixteen fields of <code class="language-plaintext highlighter-rouge">Mutex&lt;String&gt;</code>, <code class="language-plaintext highlighter-rouge">AtomicBool</code>, <code class="language-plaintext highlighter-rouge">Mutex&lt;VecDeque&gt;</code>, and <code class="language-plaintext highlighter-rouge">Mutex&lt;Instant&gt;</code>, shared by every thread. Every access to any of them was a potential race condition, and every “temporary” boolean was a state machine in denial.</p>

<p>Worse was the multiplexing. One pair — a <code class="language-plaintext highlighter-rouge">transliterated_text</code> string plus a <code class="language-plaintext highlighter-rouge">vad_finish.notify()</code> signal — carried <strong>five distinct meanings</strong>:</p>

<ol>
  <li>Transcribed user speech</li>
  <li>System notifications injected into the conversation</li>
  <li>Memory-consolidation results</li>
  <li>Questions arriving from external ACP agents</li>
  <li>The initial greeting at startup</li>
</ol>

<p>When the LLM task woke up on that <code class="language-plaintext highlighter-rouge">Notify</code>, it read whatever string happened to be in the mutex and could not tell which of the five worlds it was waking into. Text meant for one purpose could be overwritten by another producer before the consumer read it. This is what happens when a channel has no type: semantics leak into convention, and convention leaks into bugs.</p>

<p>Meanwhile, cancellation was one <code class="language-plaintext highlighter-rouge">broadcast</code> used for two very different intents: “the user just interrupted me” (barge-in, act within milliseconds) and “consolidation needs the LLM to pause politely.” Same signal, opposite urgencies, no priority between them.</p>

<h2 id="the-patterns-with-names-and-dates">The patterns with names and dates</h2>

<p>Before redesigning, I looked at what the field already knew.</p>

<p><strong>Statecharts</strong> (David Harel, 1987) formalized what my boolean flags were fumbling toward: a system’s behavior should be declared as an explicit finite state machine, with states, events, and legal transitions — not inferred from a cloud of independent bits. Seneschal already had obvious states (Idle, Listening, Thinking, Speaking); nothing in the code said so.</p>

<p><strong>The Actor model</strong> (Carl Hewitt, 1973) supplied the alternative to <code class="language-plaintext highlighter-rouge">SharedSession</code>: components with <em>private</em> state that communicate only by passing messages. Actors never share mutable state — which is precisely the property <code class="language-plaintext highlighter-rouge">SharedSession</code> violated.</p>

<p><strong>Pipecat</strong>, a production voice-agent framework, draws the sharpest practical line: pipelines carry two kinds of frames. <em>Data frames</em> (audio, text, tokens) flow forward; <em>control frames</em> (start, cancel, interrupt) can flow in any direction. My system mixed both in the same channel — the transcript string carried user data <em>and</em> system control notifications.</p>

<p><strong>ARINC 653</strong>, the avionics standard for time- and space-partitioned systems, forced me to write down what each stage actually needs:</p>

<table>
  <thead>
    <tr>
      <th>Priority</th>
      <th>Component</th>
      <th>Deadline</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>CRITICAL</td>
      <td>VAD detection + barge-in</td>
      <td>&lt; 50 ms</td>
    </tr>
    <tr>
      <td>HIGH</td>
      <td>STT transcription</td>
      <td>200–500 ms</td>
    </tr>
    <tr>
      <td>MEDIUM</td>
      <td>LLM inference + TTS</td>
      <td>500–1000 ms</td>
    </tr>
    <tr>
      <td>LOW</td>
      <td>Consolidation, memory</td>
      <td>no deadline</td>
    </tr>
  </tbody>
</table>

<p>High-priority work must be able to interrupt low-priority work, never the reverse. One broadcast signal serving both barge-in and a polite consolidation pause violates that rule by construction.</p>

<h2 id="the-wrong-fix-a-supervisor">The wrong fix: a supervisor</h2>

<p>The textbook reflex against shared mutable state is a coordinator: one task that owns all state, receives every event, and re-emits commands to the workers. A tidy <code class="language-plaintext highlighter-rouge">PipelineSupervisor</code>. A serialization point with a nice name.</p>

<p>I rejected it, and the reason is a number: the LLM streams hundreds of tokens per second. A supervisor sitting between the LLM task and the sentence task would be a single-threaded funnel processing every <code class="language-plaintext highlighter-rouge">LLMToken</code> frame, every sentence boundary, every interruption — adding a hop, a queue, and a contention point precisely in the path that feeds the “first word in under a second” budget. Coordinators don’t remove races; they just make you wait in line.</p>

<h2 id="the-right-shape-typed-channels-plus-a-watch-based-fsm">The right shape: typed channels plus a watch-based FSM</h2>

<p>The redesign kept the actors — the task decomposition was already correct — and replaced only <em>how</em> they communicate. Two planes:</p>

<p><strong>Control plane.</strong> One <code class="language-plaintext highlighter-rouge">tokio::sync::watch&lt;PipelineState&gt;</code> channel holds the global state as an enum:</p>

<div class="language-rust highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">pub</span> <span class="k">enum</span> <span class="n">PipelineState</span> <span class="p">{</span>
    <span class="n">Idle</span><span class="p">,</span>
    <span class="n">Listening</span> <span class="p">{</span> <span class="n">utterance_id</span><span class="p">:</span> <span class="nb">u64</span> <span class="p">},</span>
    <span class="n">Thinking</span>  <span class="p">{</span> <span class="n">utterance_id</span><span class="p">:</span> <span class="nb">u64</span> <span class="p">},</span>
    <span class="n">Speaking</span>  <span class="p">{</span> <span class="n">utterance_id</span><span class="p">:</span> <span class="nb">u64</span> <span class="p">},</span>
    <span class="n">Paused</span>    <span class="p">{</span> <span class="n">reason</span><span class="p">:</span> <span class="n">PauseReason</span> <span class="p">},</span>
<span class="p">}</span>
</code></pre></div></div>

<p>A <code class="language-plaintext highlighter-rouge">watch</code> channel keeps only the <em>latest</em> value: one writer at a time, any number of readers, no queue, no backlog. <strong>Each actor that owns a transition writes it directly</strong> — the VAD actor moves the state to <code class="language-plaintext highlighter-rouge">Listening</code>, the LLM actor to <code class="language-plaintext highlighter-rouge">Thinking</code>, the TTS actor to <code class="language-plaintext highlighter-rouge">Speaking</code>. No coordinator sits in between. The sixteen booleans collapse into one enum variant: <code class="language-plaintext highlighter-rouge">llm_busy</code> <em>is</em> <code class="language-plaintext highlighter-rouge">Thinking</code>, <code class="language-plaintext highlighter-rouge">consolidation_active</code> <em>is</em> <code class="language-plaintext highlighter-rouge">Paused { Consolidation }</code>. Illegal combinations like <code class="language-plaintext highlighter-rouge">llm_busy &amp;&amp; !listening</code> stop being representable.</p>

<p>Cancellation splits into two broadcasts with different writers and different audiences: <code class="language-plaintext highlighter-rouge">barge_in_tx</code> (only the VAD sends it; every actor cancels immediately) and <code class="language-plaintext highlighter-rouge">pause_tx</code> (only consolidation sends it; only the LLM listens). Priority bands, made structural.</p>

<p><strong>Data plane.</strong> Every flow gets its own typed channel:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VAD/STT  --mpsc&lt;TranscriptReady&gt;--&gt;  LLM actor
LLM      --mpsc&lt;LLMToken&gt;--------&gt;  Sentence actor
Sentence --mpsc&lt;SentenceReady&gt;---&gt;  TTS actor
</code></pre></div></div>

<p>Every frame carries an <code class="language-plaintext highlighter-rouge">utterance_id</code>, so one user turn can be traced end to end through logs and latency metrics. The five meanings that used to share one string became distinct variants — <code class="language-plaintext highlighter-rouge">TranscriptReady</code>, <code class="language-plaintext highlighter-rouge">SystemNotification</code>, <code class="language-plaintext highlighter-rouge">AgentResult</code>, <code class="language-plaintext highlighter-rouge">TextInput</code> — each with its own producer and its own semantics. Audio chunks stay on their own bounded channel, deliberately outside the frame enum: too high-volume to route.</p>

<p>A supervisor still exists — as a pure <em>observer</em>. It subscribes to the <code class="language-plaintext highlighter-rouge">watch</code> receiver and logs every transition for the TUI and diagnostics. It never sits between actors, because it never needs to: the state is already in one place, and everyone already reads it.</p>

<p>The migration was mechanical enough to tabulate — every <code class="language-plaintext highlighter-rouge">SharedSession</code> field mapped to a typed replacement (<code class="language-plaintext highlighter-rouge">transliterated_text</code> → <code class="language-plaintext highlighter-rouge">mpsc&lt;TranscriptReady&gt;</code>, <code class="language-plaintext highlighter-rouge">assistant_text</code> → <code class="language-plaintext highlighter-rouge">mpsc&lt;LLMToken&gt;</code>, <code class="language-plaintext highlighter-rouge">sentences</code> → <code class="language-plaintext highlighter-rouge">mpsc&lt;SentenceReady&gt;</code>, <code class="language-plaintext highlighter-rouge">llm_busy</code> → <code class="language-plaintext highlighter-rouge">PipelineState::Thinking</code>, and so on) until the struct stood empty and could be deleted.</p>

<h2 id="refactor-not-rewrite">Refactor, not rewrite</h2>

<p>A full rewrite onto a real actor framework — supervision trees, SCXML statecharts, priority scheduling — was estimated at two to three weeks. The incremental refactor took three to five days: define the frame enum, add the FSM and the watch channel, migrate fields one by one (build and test after each), split the cancellation signals, delete <code class="language-plaintext highlighter-rouge">SharedSession</code>.</p>

<p>The rewrite was not wrong in general — it is appropriate for a product with multiple engineers and contractual latency SLAs. It is overhead for a single-user bot on one machine whose existing task structure was already the right one. The lesson is the boring one: diagnose whether your problem is structure or mechanism. Mine was mechanism, and mechanism refactors cheaply.</p>

<h2 id="frozen-as-law">Frozen as law</h2>

<p>The final shape is now written into the project’s <code class="language-plaintext highlighter-rouge">CONSTITUTION.md</code> under the non-negotiable architecture section: pipeline state is an explicit FSM carried by a single <code class="language-plaintext highlighter-rouge">watch&lt;PipelineState&gt;</code> channel, each stage is a tokio task with private state that talks only through typed channels, and — the clause that started this whole detour — <em>no central coordinator sits on the hot path</em>. Amending either requires explicit deliberation.</p>

<p>Writing the shape of the system down, after killing the shared session, is what keeps the next contributor (or the next agent) from helpfully reintroducing the supervisor.</p>

<p>Two rules, earned the slow way:</p>

<ol>
  <li><strong>Shared mutable state is not a performance problem, it is a semantics problem.</strong> <code class="language-plaintext highlighter-rouge">Mutex&lt;String&gt;</code> + <code class="language-plaintext highlighter-rouge">Notify</code> was not “slow” — it was ambiguous. Types are the fix; locks are a placebo.</li>
  <li><strong>A coordinator is a bottleneck wearing a diagram.</strong> If the global state is one small latest-value enum, a <code class="language-plaintext highlighter-rouge">watch</code> channel gives everyone a view of it for free — and the coordinator’s inbox is exactly the hot path you cannot afford.</li>
</ol>]]></content><author><name>Daniel Vela</name></author><summary type="html"><![CDATA[Seneschal is a real-time voice assistant: a single Rust binary where a microphone, a VAD, Whisper, an LLM streaming hundreds of tokens per second, a sentence splitter, and a TTS engine all have to cooperate within a few hundred milliseconds. When I sat down to audit how those components actually talked to each other, I found two things: a struct that had quietly become a battlefield, and an instinctive “fix” — a central supervisor — that would have made things dramatically worse.]]></summary></entry></feed>